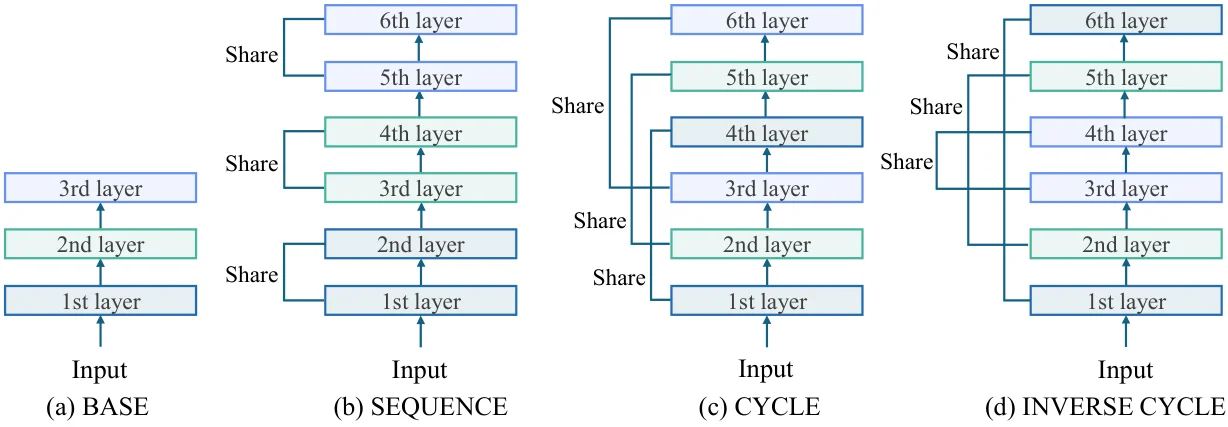
Boosting LLM Reasoning Without Adding Parameters: The Principle of 'Virtual Logic Depth'
Google DeepMind has introduced 'Virtual Logic Depth,' a scaling dimension that boosts LLM reasoning capabilities without increasing parameter size by looping da
TAU-HOME.COM stories tagged LocalLLM.
Google DeepMind has introduced 'Virtual Logic Depth,' a scaling dimension that boosts LLM reasoning capabilities without increasing parameter size by looping da
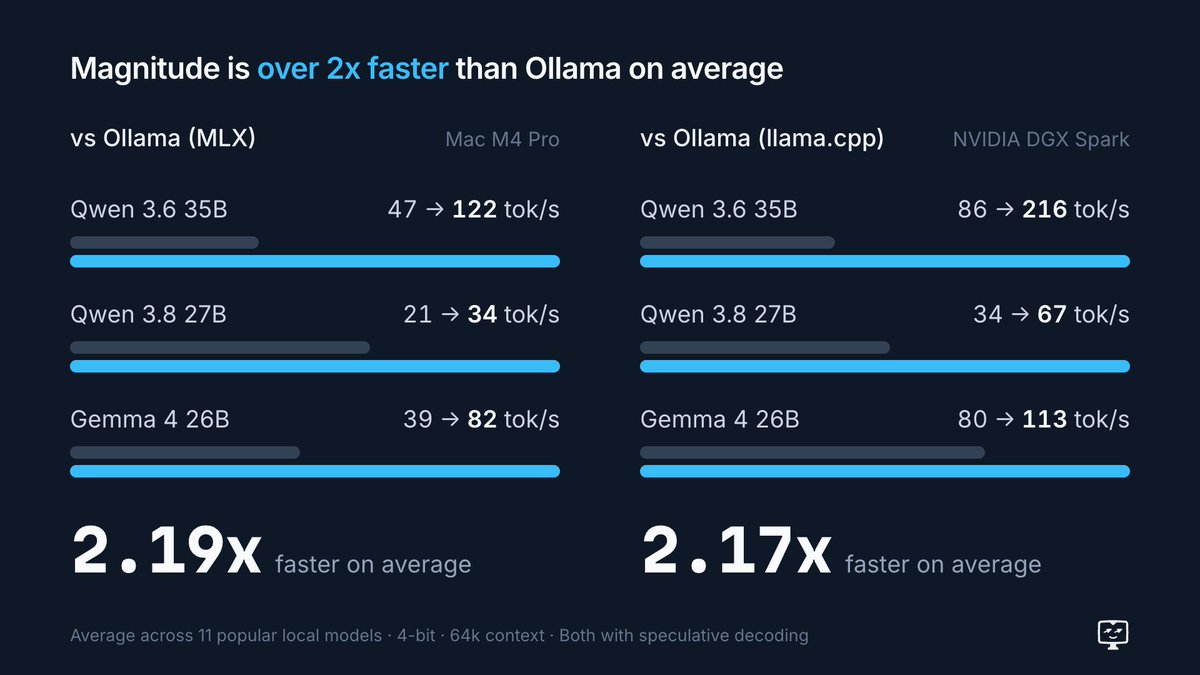
Tom Greenwald has announced Magnitude, a 100% free and open-source local LLM inference engine that auto-tunes compute kernels to user hardware, averaging 2.19x
Ranked #2 on Hugging Face trending, 'Humanizer' is an open-source 12B local model designed to rewrite AI-generated drafts—such as emails, essays, and reports—in
Local LLM fleet dashboard sparkDash v2.0 is out with a redesigned UI, direct model launches from cards, Decode/Prefill/Quality/Tool Eval benchmark pages, and ne
Ghost AI has unveiled Core, a personal AI computer running local models 24/7 on-device. Powered by NVIDIA RTX PRO 4000 Blackwell SFF, it hits 87 tok/s on Qwen-3
A benchmark of Qwen3.8-Flash-Next NVFP4 on a single 128GB DGX Spark demonstrates 1M context with FP8 KV cache, 4-stream concurrency, and full multimodal input s
Community GGUF quantizations for Aleph Alpha's 78B MoE model Kolibri-1 are now available, achieving 13-15 TPS on a Ryzen 7 7800X3D CPU using 128GB RAM and patch
Empirical benchmark results comparing local LLM inference speeds (tok/s) and Time to First Token (TTFT) across RTX 5060 Ti (16GB), RTX 5090 (32GB), and GB10 (12
Open-source local LLM engine Strata v0.1.34 adds official AMD GPU acceleration on Windows and a built-in MCP server for direct AI coding agent integration.
Coding agent harness 18.3.0 slashes base prompt token usage from ~30k to 10k for faster local model prefill, consolidates tools into read/write/bash, enables de
Magnitude profiles your PC hardware, ranks local LLMs with estimated tok/s, applies speculative decoding, and bridges local models to Pi, OpenCode, and Claude C
Static 98.2% retention benchmarks miss agentic coding breakdown. How switching to ISTA-DASLab GSQ-RCO IQ2_XS (2.50 bpw) on a 12GB RTX 3080 Ti restores task reli
The dealignai team has released a weight-level abliterated CRACK build of PrismML's 5.95GB ternary Qwen3.8-27B model Bonsai 2, eliminating refusal behavior with
LocalAI runs LLMs, voice, vision, and agents locally without cloud API fees or data leakage. Explore OpenAI-compatible endpoints, pluggable backends, and CPU op
An uncensored GGUF build of Nex-N2.5-mini (IQ4_XS) enables local execution on an 18GB GPU. Explore its 35B MoE architecture, 262K context, vision mmproj, and ll
MiaAI-Lab has released an open-source one-click serving kit that sets up Qwen3.8-27B using turboderp's EXL3 quantization on a single 16GB VRAM NVIDIA GPU with l
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285