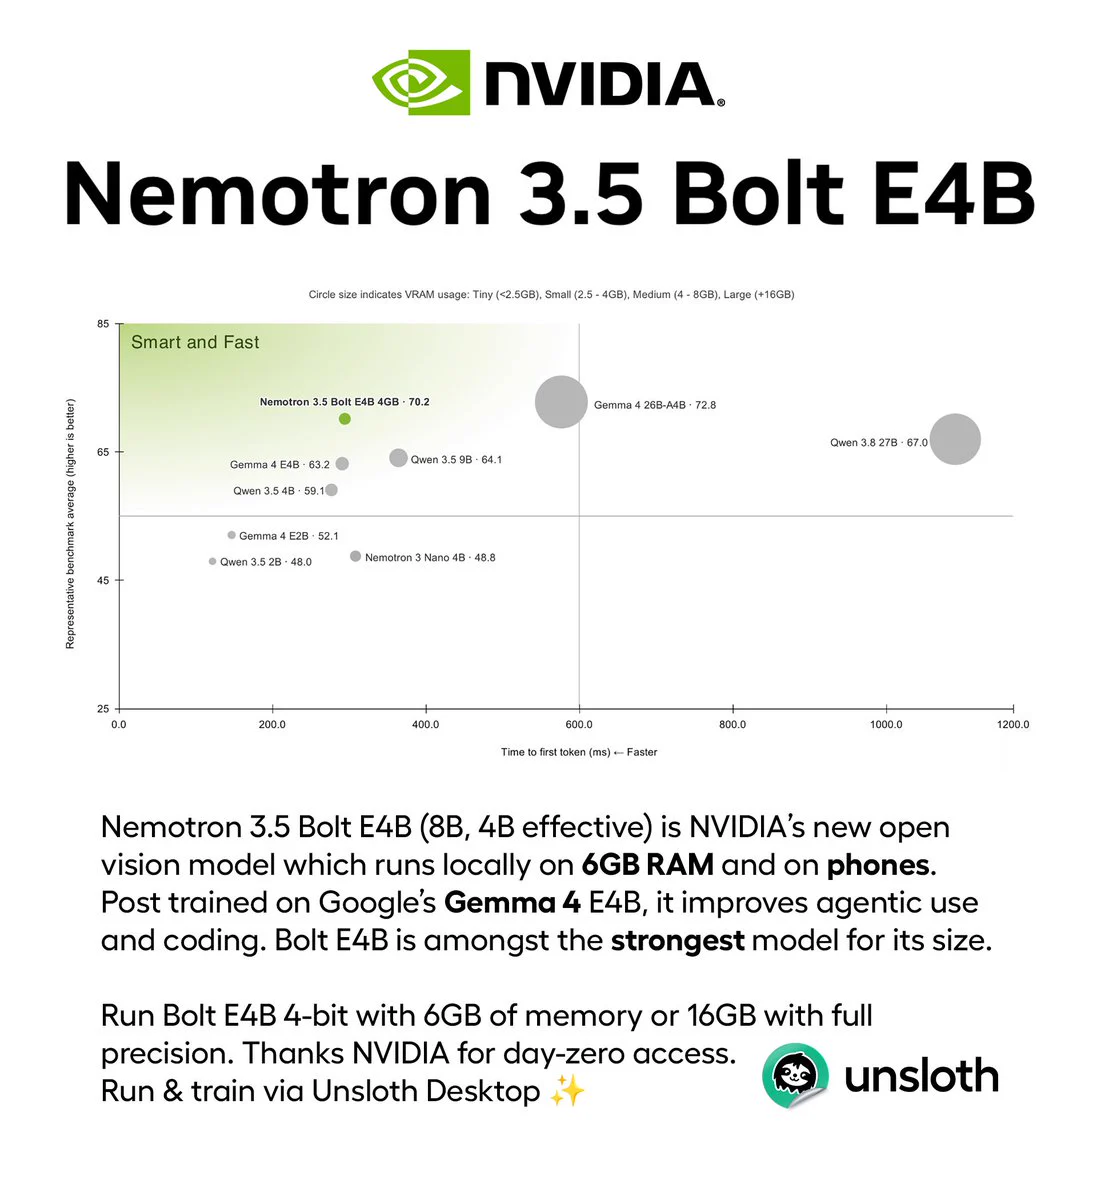
NVIDIA Nemotron 3.5 Bolt E4B: October 23 Model Card and Unsloth's Edge Deployment Guide
NVIDIA's official October 23 release and text-in/text-out endpoint specifications, alongside Unsloth's separate October 24 guidance on 6GB devices and GGUF.
TAU-HOME.COM stories tagged GGUF.
NVIDIA's official October 23 release and text-in/text-out endpoint specifications, alongside Unsloth's separate October 24 guidance on 6GB devices and GGUF.
Unsloth has released Dynamic 3.0 GGUF quantization weights for Qwen3.8-27B, introducing sizes from 6.2GB to 22GB. Key verified changes and memory caveats are de
UkisAI's reasoning-efficient Swift 1.5 Qwen3.8-27B gets an ultra-light 2-3-bit GSQ-RCO GGUF packaging for llama.cpp, plus IQ3_S 16GB benchmark reports.
A measured demo in which the 2.4-bit Mirai S Qwen3.8-27B quantized model produced a 1,005-line single-HTML 3D hamster simulation from one prompt plus three foll
Mitsuba and its uncensored HiMitsuba LoRA compress Qwen3.8-27B into a 7.3GB 1.58-bit VLM, enabling fast local image analysis and prompt generation for ComfyUI o
Community GGUF quantizations for Aleph Alpha's 78B MoE model Kolibri-1 are now available, achieving 13-15 TPS on a Ryzen 7 7800X3D CPU using 128GB RAM and patch
A practical guide to running uncensored Qwen-Image-2.1 locally in ComfyUI by pairing the 4.68GB Q4_K_M DiT backbone with the community Heretic text encoder on 8
The dealignai team has released a weight-level abliterated CRACK build of PrismML's 5.95GB ternary Qwen3.8-27B model Bonsai 2, eliminating refusal behavior with
An uncensored GGUF build of Nex-N2.5-mini (IQ4_XS) enables local execution on an 18GB GPU. Explore its 35B MoE architecture, 262K context, vision mmproj, and ll
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285