Running a 125B MoE on a Single RTX 4090: Qwen3.8-Flash-Next Hybrid Inference Report
A community report claims Qwen3.8-Flash-Next, a 125B MoE model, runs on a single RTX 4090 with system-RAM offload. Here are the verified conditions and caveats.
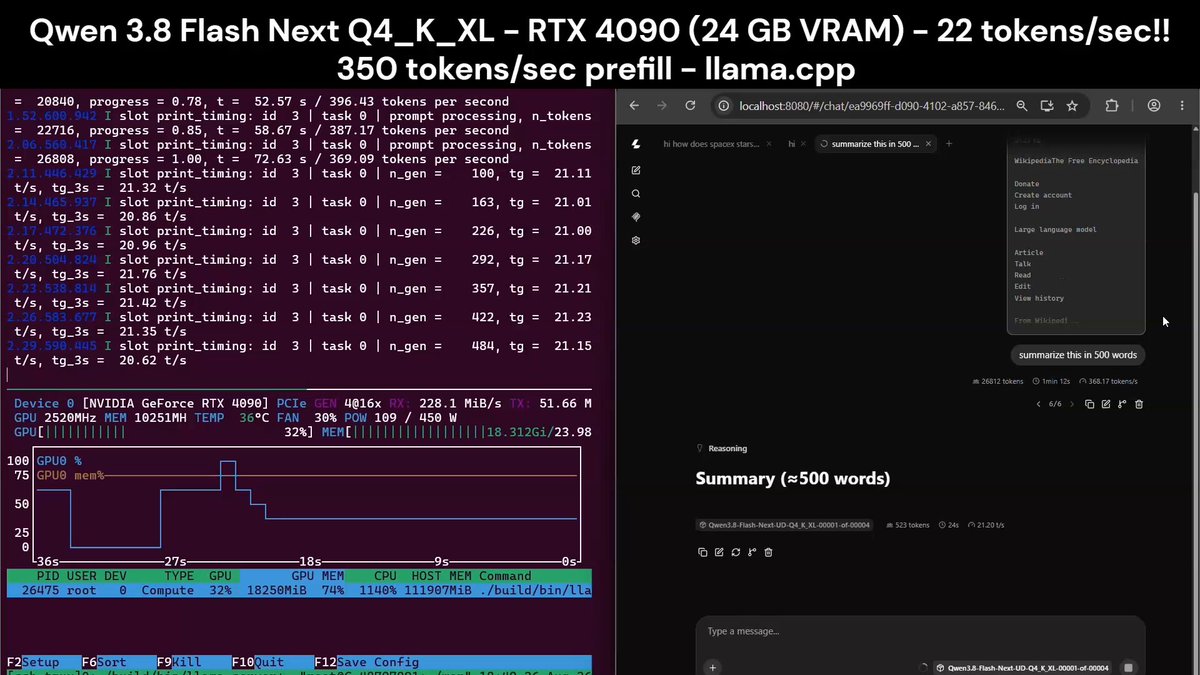
On October 3, 2026, X user @Oluwaphilemon1 (FHILY) summarized a community report claiming the 125B-class MoE model Qwen3.8-Flash-Next runs on a single RTX 4090 with system-RAM offload. The reported figures are roughly 21 tok/s decode, roughly 364 tok/s prefill, and 250K context. These are third-party reports, not official benchmarks.
Image source: video attached to the X post by @Oluwaphilemon1
The point of the report is not that "the whole 125B fits inside the 4090." It is the combination of a sparse MoE architecture with hybrid inference. According to Qwen's official README and tech report, Qwen3.8-Flash-Next pairs a 125B-parameter main model with an additional 51B N-gram embedding table, activating roughly 6B parameters per token. The GPU handles the parts where compute and memory bandwidth matter most, while the MoE experts live in system RAM.
Reported setup and numbers: check the conditions before reproducing
The original post describes this configuration:
- GPU: a single RTX 4090 with 24GB VRAM
- System RAM: 110GB DDR4
- Context: 250K
- Decode: ~21 tok/s, prefill: ~364 tok/s
- Not used: no MTP, no DFlash, no KV-cache quantization
Two caveats matter. First, every throughput figure is a cited third-party run, not an officially measured value. Second, Jatin Garg asked in a reply how time-to-first-token behaves at 250K context without KV-cache, and no author answer exists within the collected evidence. Readers eyeing extreme long-context use should treat TTFT as still unanswered here.
Separate community records point the same way. A gist by ryan4yin documents a llama.cpp setup on an RTX 4090 24GB with 96GB DDR5 running a UD-IQ3_XXS GGUF quant of about 82GB, and indrasmirror.au reports lifting MoE decode on a single 4090 from the 23 t/s range to the 65 t/s range with a GPU-resident expert cache plus load-mode tuning. The common starting line is "one 4090 plus large system RAM plus low-bit quantization plus offload."
The Mac branch: Sushi 2-bit pack with disk streaming
A follow-up post from the same author covers the practical path on 32GB unified-memory Macs. Sushi's 2-bit pack streams the model directly from disk instead of requiring the whole model in memory, covering machines from M1 through M6.
- Model: Qwen3.8-Flash-Next, Sushi 2bpw pack
- Hardware: Mac with 32GB unified memory
- Context: ~66K with disk streaming
- Reported performance (M1 Max): ~200 tok/s prefill, ~18 tok/s generation
These figures are also third-party reports, and they assume a 2-bit low-precision pack with disk streaming rather than full-precision loading. It is a realistic fallback for memory-constrained Macs, but the emphasis is on "it runs," not on speed.
Checklist before putting this report to work
- The model is a sparse MoE: 125B total, ~6B active per token, plus a separate 51B N-gram embedding table. Read settings through that structure.
- A single-RTX-4090 run presupposes on the order of 96GB of system RAM across multiple community records. The 110GB DDR4 report sits on the same line.
- The reported condition explicitly excludes MTP, DFlash, and KV-cache quantization. Further speedups via expert caching or speculative decoding, as indrasmirror.au describes, belong to a separate tuning step.
- At extreme contexts like 250K, TTFT is the deciding factor, and this report has no answer for it. Validate incrementally from short contexts before feeding long documents.
- The official serving recipe (sglang-based) still assumes tensor-parallel distribution and a 262,144 native context. A single consumer GPU run remains a community workaround.
Original source
- @Oluwaphilemon1 original post (RTX 4090 report): X post
- @Oluwaphilemon1 follow-up post (32GB Mac + Sushi 2-bit): X post
- Qwen3.8-Flash-Next official repository: QwenLM/Qwen3.8-Flash-Next