A 6-Step Workflow for Producing AI Sitcoms and Short Dramas with Seedance 2.5
A complete 6-stage production pipeline from planning to final cut, featuring tips on generating dialogue, facial expressions, and physical gestures simultaneous
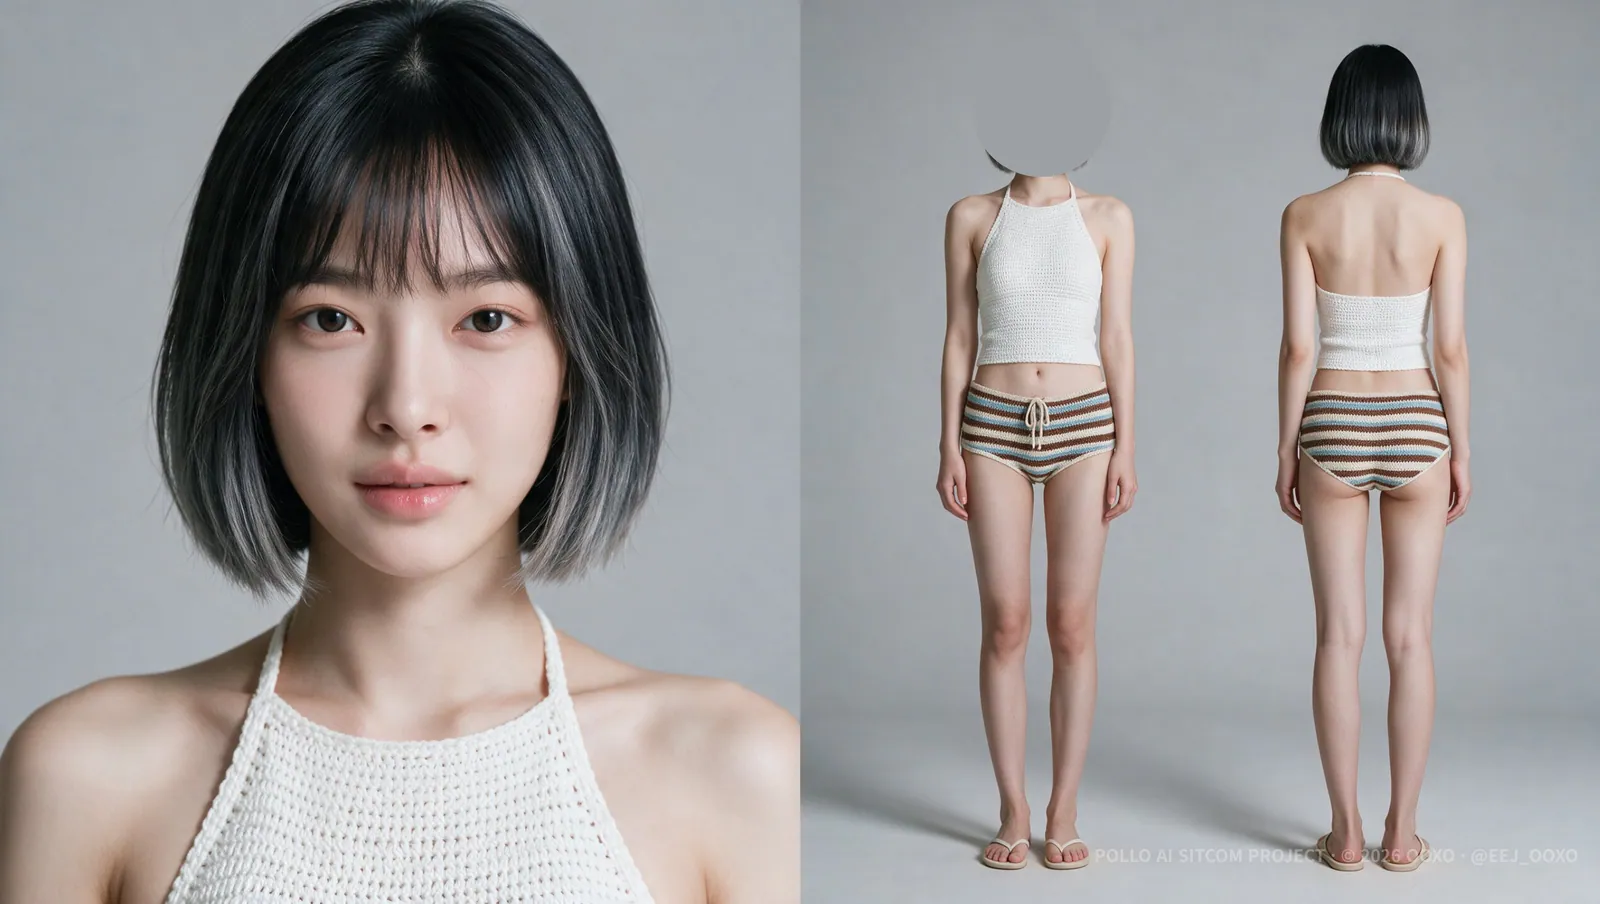
AI video creator OOXO (@EEJ_OOXO) has shared an operational workflow and practical production tips for crafting AI-driven sitcoms and short dramas using the video generation model Seedance 2.5.
Image source: https://x.com/EEJ_OOXO/status/2096105636815925422
While generative video tools that turn text prompts or still images into short clips have become widespread, assembling a cohesive sitcom or short-form narrative drama remains difficult. Characters often morph inconsistently between shots, and decoupled voices and lip movements frequently break dramatic immersion. The 6-step framework and direct dialogue-performance synthesis method outlined by OOXO provide a clear roadmap for resolving these recurring bottlenecks in generative narrative video.
The 6-Step Production Pipeline for Sitcoms and Short Dramas
The end-to-end production process is organized into six consecutive stages from initial concept to master delivery:
- Planning — Scenario, Sequences, and Scenes: Outline the overarching narrative arc, segment the story into dramatic sequences, and define individual visual scenes with specific setting parameters.
- Collecting Reference Images and Footage: Gather visual benchmarks covering target lighting, framing, character styling, interior architecture, and color palettes.
- Asset Generation: Establish visual consistency before rendering final motion by creating base character portraits, costume standards, and key environments.
- Video Generation Combined with Parallel Editing: Render scene clips with Seedance 2.5 while placing them directly onto the timeline to assemble a rough cut in real time.
- Music Generation: Generate atmospheric scoring and sound effects once the dramatic cut is formed.
- Color Inspection and Final Cut: Check color uniformity across shots, fine-tune pacing and cut points, and finalize the sequence.
Why Background Score Generation Moves to the Late Stage
In conventional AI music video pipelines, generating the track first is standard practice because cuts and pacing must align tightly with tempo and beats.
For narrative drama, however, the music step moves back to step five. Dialogue cadence, actor breathing, and dramatic pacing must dictate the visual rhythm of the edit. Background tracks should never overpower voice clarity. In this project, music was omitted entirely throughout the dialogue-heavy drama sections and applied only to the closing promotional section. Deferring music generation allows the natural pacing of the scene to breathe without artificial tempo constraints.
The Tactical Edge of Parallel Generation and Editing
Another key technique in this workflow is merging video generation and timeline assembly into step four rather than treating them as disconnected linear milestones.
Instead of generating every single cut in isolation before launching video editing software, placing newly rendered clips onto the timeline immediately lets the editor evaluate continuity on the fly. Camera angles, character eye lines, and physical momentum from the previous shot can be adjusted directly in the prompt or seed parameters for the next cut. This tight feedback loop eliminates the costly cycle of generating dozens of mismatched clips only to discover continuity errors during post-production.
Skipping Post-Dubbed Lip-Sync for Native Audio-Visual Synthesis
The most significant technical takeaway from this workflow is the deliberate choice to avoid dedicated post-production lip-sync utilities.
A common industry workflow involves rendering a silent video clip first and then running external neural lip-sync tools to align mouth movements to a prerecorded voice track. However, OOXO advises against relying on post-dubbed lip-sync for narrative drama whenever possible.
External warping tools that adjust only the mouth region often produce an artificial aesthetic because they fail to synchronize micro-expressions, breathing tension, eye narrowing, neck muscle movements, and physical body gestures with the spoken words. By relying on Seedance 2.5 to output dialogue, vocal performance, and physical acting all at once, the resulting footage preserves organic coherence across the entire upper body and face.
Preserving Native Output Tones Without Additional Grading
During the final finishing pass in step six, separate manual color grading was omitted. Leaving the color grade untouched preserved the authentic textural output and visual consistency of Seedance 2.5, which matched the commercial demonstration goals of this sponsored video.
Whether to retain native rendering aesthetics or introduce custom Look-Up Tables (LUTs) in post-production depends on client requirements and creative intent. Treating model output fidelity as a deliberate stylistic choice simplifies the finishing stage significantly.
Original source
- OOXO Official X Post: Seedance 2.5 Video Production Framework Breakdown
- cleanup2eok Shared Thread: Practical AI Sitcom and Short Drama Production Sequence