Swift 1.5 GSQ-RCO GGUF Release Packs 27B-Class Qwen3.8 for 16GB GPUs
UkisAI's reasoning-efficient Swift 1.5 Qwen3.8-27B gets an ultra-light 2-3-bit GSQ-RCO GGUF packaging for llama.cpp, plus IQ3_S 16GB benchmark reports.
TAU-HOME.COM stories tagged llama.cpp.
UkisAI's reasoning-efficient Swift 1.5 Qwen3.8-27B gets an ultra-light 2-3-bit GSQ-RCO GGUF packaging for llama.cpp, plus IQ3_S 16GB benchmark reports.
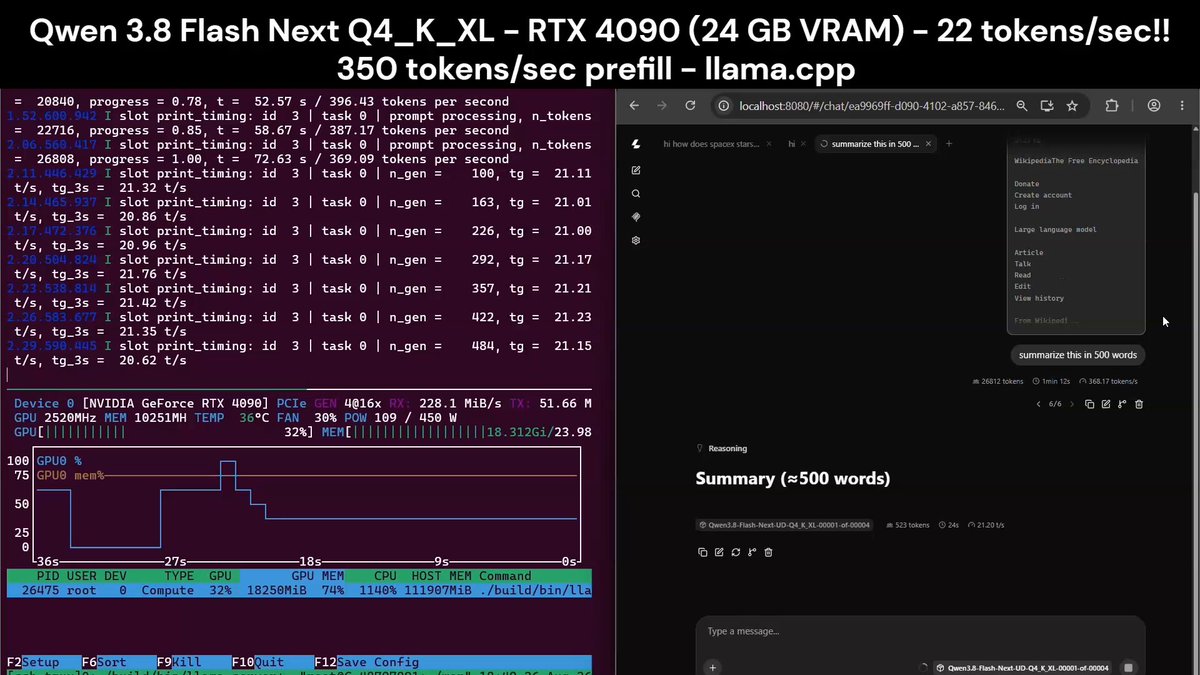
A community report claims Qwen3.8-Flash-Next, a 125B MoE model, runs on a single RTX 4090 with system-RAM offload. Here are the verified conditions and caveats.
Run local LLMs, generate images, transcribe audio, and cluster devices without cloud subscriptions. A curated guide to 10 essential GitHub repos like llama.cpp,
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285