How to Access GLM 5.3 Flash Uncensored for Free on xplabs
A quick setup guide and key caveats for using the uncensored GLM 5.3 Flash model for free on the xplabs web platform backed by a shared 13M TPM pool.
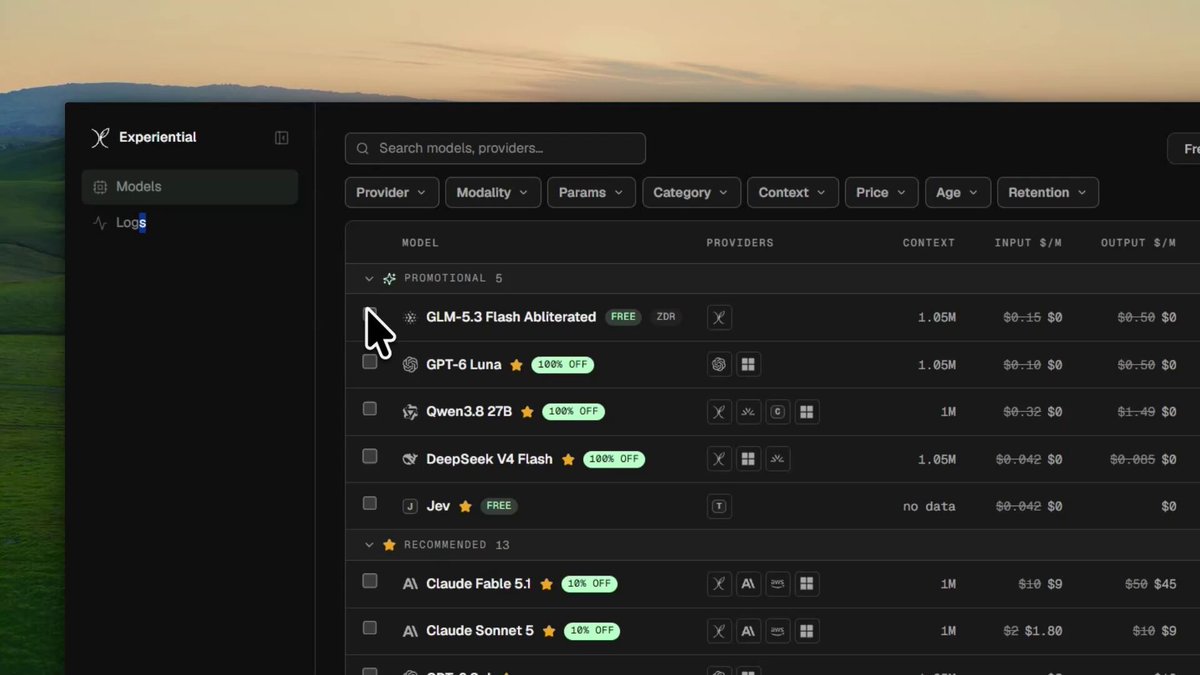
Tech creator Sakata (@sakatayasha) has shared a quick setup guide to access the uncensored build of Z.ai's 320B hybrid MoE model, GLM 5.3 Flash, completely free on the xplabs platform. The endpoint allows users to get started directly in a web browser in under a minute without paid subscriptions or complex API configurations.
Image source: X @sakatayasha
This guide covers the simple three-step access procedure on the xplabs web platform, alongside important infrastructure constraints including the shared 13M TPM (Tokens Per Minute) pool and usage considerations.
320B Hybrid MoE and Weight-Level Uncensored Architecture Overview
GLM 5.3 Flash is Z.ai's (Zhipu AI) next-generation 320B parameter foundation model (with approximately 18B active parameters per token) built on a hybrid Mixture-of-Experts (MoE) architecture. It combines sparse and linear attention for high efficiency, featuring a native 1M token context window and native multimodal vision capabilities.
The uncensored edition hosted on xplabs is served from an abliterated open checkpoint where refusal directions have been permanently removed directly at the tensor weight level, rather than relying on shallow prompt jailbreaks or runtime hooks. This eliminates benign-request over-refusal during creative writing, security research, and unrestricted code analysis.
Step-by-Step Guide: Accessing GLM 5.3 Flash on xplabs
Getting started with GLM 5.3 Flash Uncensored on the xplabs platform involves three straightforward steps:
- Navigate to the Platform: Open the official platform URL in your browser (
https://platform.xplabs.ai). - Select the Model: Choose GLM 5.3 Flash (Uncensored) from the model selection menu.
- Start Generating: Enter your prompt or test queries in the workspace and begin generating responses immediately.
No credit card registration or complex setup steps are required to start testing in the browser interface.
Shared 13M TPM Pool and Usage Caveats
When utilizing this free endpoint for exploration or research, keep the following operational constraints in mind:
- Shared 13M TPM Pool: The service runs on a collective 13 million tokens per minute capacity shared among all active users. Expect slower response times and reduced throughput during peak traffic periods.
- Adult / Research Advisory (Adults Only): Because safety guardrails and refusal filters have been ablated at the weight level, the model produces unfiltered raw completions, making it suitable specifically for adult users and responsible research.
- Prototyping vs. Production: As a shared public resource subject to peak congestion, it is best suited for exploratory testing, evaluation, and prototyping rather than mission-critical production pipelines.
Original source
- Sakata (@sakatayasha) X Post: GLM 5.3 Flash Uncensored Free Access Guide