How to Access Free Uncensored GLM 5.3 Flash on xplabs in Under 1 Minute
A quick guide to accessing the 320B-parameter uncensored GLM 5.3 Flash model hosted for free on xplabs via an 8xH100 GPU node with a shared 13M TPM pool, includ
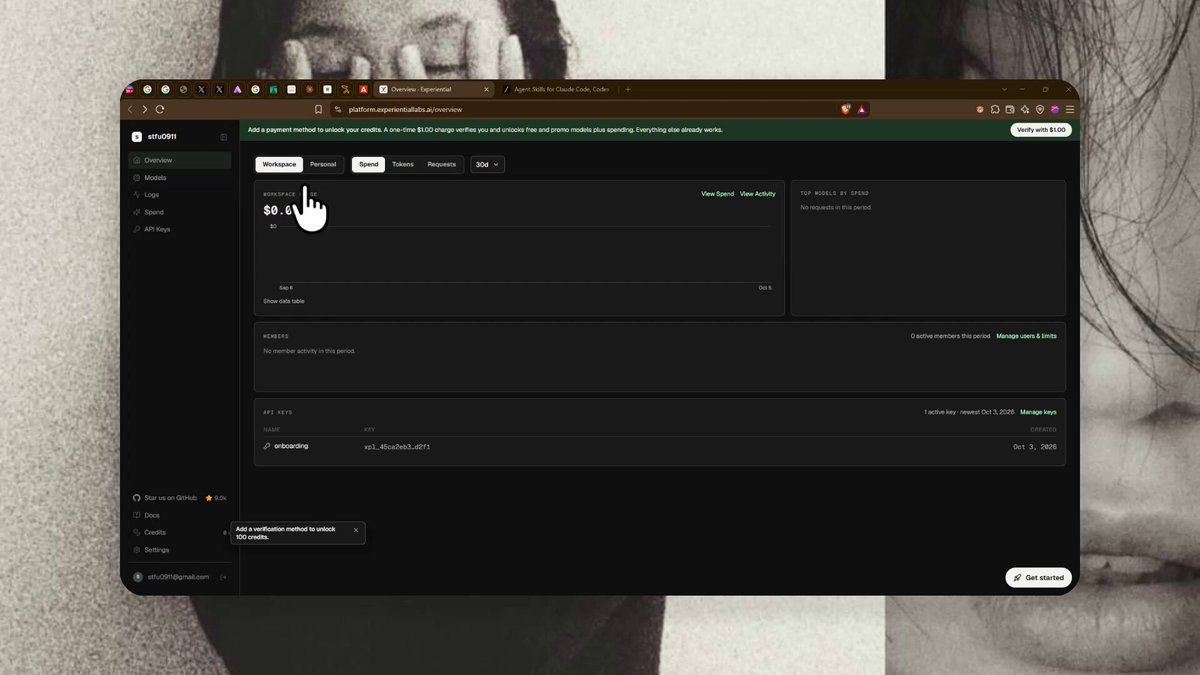
On October 5, 2026, AI creator Forha (@Forhanvv) shared an actionable tip on X (formerly Twitter) detailing how to access and test the uncensored 320B-parameter foundation model GLM 5.3 Flash for free on the xplabs web platform in under one minute, without requiring complex local environments or paid subscriptions.
Image source: @Forhanvv / X
GLM 5.3 Flash is built upon Zhipu AI's (Z.ai) 320B-parameter foundation model architecture (featuring approximately 18B active parameters per token in a Mixture-of-Experts design). The specific version hosted on xplabs is the weight-level uncensored FP8 release by dealignai (dealignai/GLM-5.3-Flash-UNCENSORED-FP8), where standard refusal mechanisms and safety over-refusals have been permanently ablated directly within the model weights. Independent developer Silen Naihin (@silennai) rented an 8xH100 GPU node for several months, optimized the model stack, and opened it to the public for free via the xplabs platform.
How to Access (Under 1 Minute)
The access process shared by Forha (@Forhanvv) is entirely browser-based and does not require complex setup or software installations:
- Open the official xplabs platform in your web browser:
https://platform.xplabs.ai. - Start interacting with the model directly in the web chat interface.
Preserving the original step numbering from the source post, this streamlined workflow allows developers and researchers to quickly test the uncensored 320B model without waiting for API keys or setting up multi-GPU local hosting.
Important Constraints and Considerations
Because this endpoint is a free, community-hosted resource running on a dedicated hardware node, users should keep several operational limitations in mind:
- Adults Only Restriction: With safety refusal behaviors ablated at the weight level, access is restricted to adult users who must adhere to legal and ethical safety responsibilities.
- Shared 13M TPM Pool: The service operates on a shared pool of 13,000,000 TPM (Tokens Per Minute) across all concurrent active users.
- Traffic-Dependent Latency: Running on a single 8xH100 GPU node, response latency and token generation speeds may decrease during peak traffic hours (peak throughput reaches ~360 TPS).
Model Architecture and Infrastructure Background
Unlike superficial prompt jailbreaks or system wrapper templates, the uncensored GLM 5.3 Flash release employs permanent weight-level intervention:
- Native FP8 Acceleration: The model operates in native FP8 precision on NVIDIA Hopper (H100) GPUs, maximizing inference throughput while maintaining model accuracy.
- Specialized Workloads: It is particularly well-suited for legitimate cybersecurity research, vulnerability triage, and complex coding tasks that are frequently blocked by over-cautious commercial safety filters.
- Community Infrastructure: As this is an independently funded GPU node hosted by Silen Naihin, long-term availability and performance depend on ongoing compute resources and community traffic loads.
Original source
- Forha (@Forhanvv) on X: https://x.com/Forhanvv/status/2107015032756445379