Testing Triple References for Seedance 2.0: Character, Color, and Depth Boards
Creator bunpinku tested Seedance 2.0 on NewTake using character, color, and depth boards with camera prompt alignment in a 35-second action breakdown.
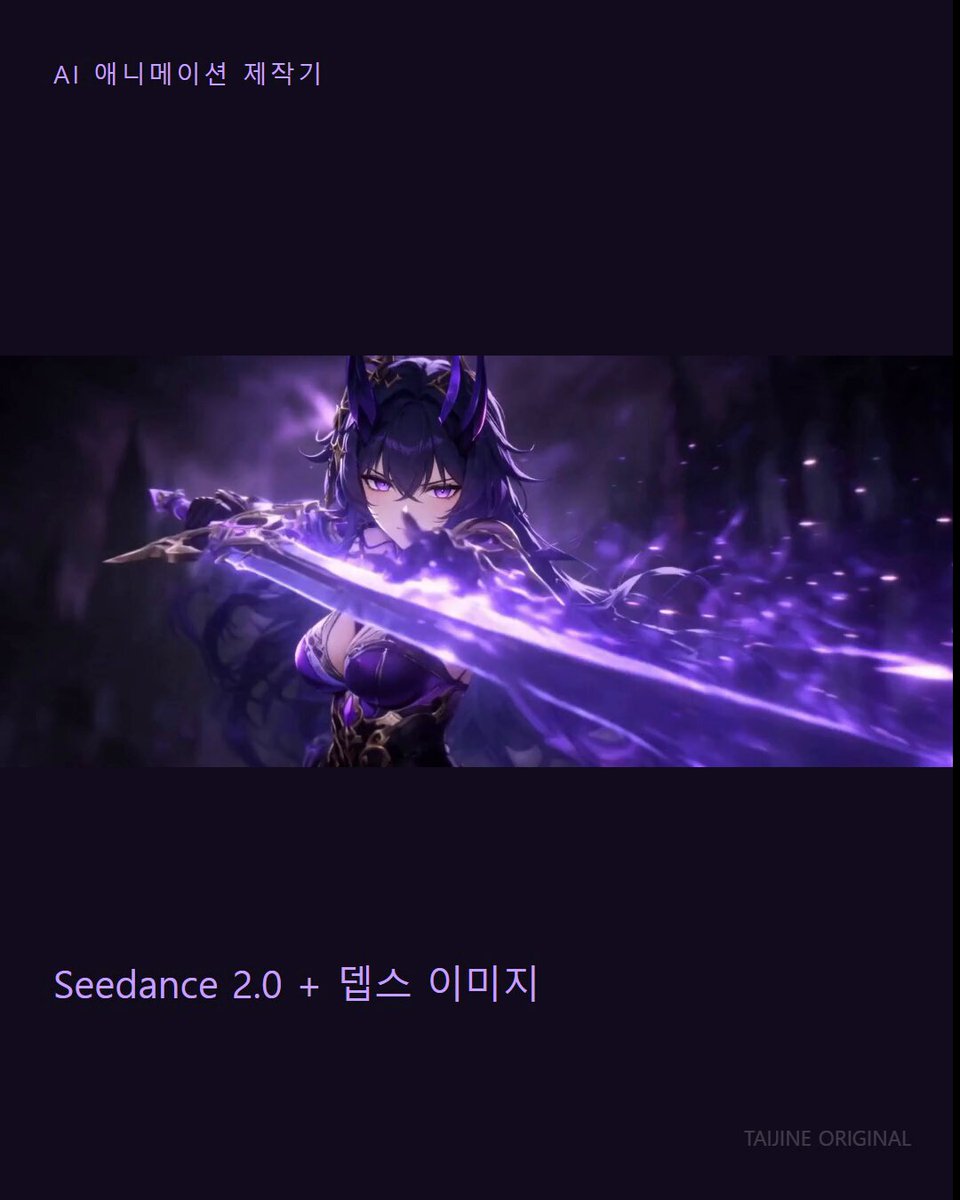
On October 3, 2026, X creator bunpinku (@bun_pingku) shared an experimental action animation testing what happens when depth images are supplied as references in AI animation. Built using the Seedance 2.0 model on the NewTake platform, the author summarized the input references and output shots in a 35-second behind-the-scenes video breakdown.
Image source: bunpinku(@bun_pingku) via X
The author explained that three distinct reference images were assigned specialized roles: character images specified "who is fighting," color boards defined "what they look like," and depth boards indicated "where and how close they are located." The accompanying prompt instructed the model to align with the camera angle and framing of the depth board.
The Divided Roles of Three Reference Images
The author's breakdown delegates visual control across three separate reference inputs:
- Character Image → Who is fighting: Establishes character identity and features.
- Color Board → What they look like: Dictates color palette and visual appearance.
- Depth Board → Where and how close they are: Conveys spatial layout, positioning, and distance from the camera.
The creator shared side-by-side comparisons of the reference inputs alongside the generated video clips. While noting that not every cut translated perfectly, the author observed that reviewing the reference inputs alongside the resulting outputs offered compelling results.
Directing Prompts to Follow Depth Board Camera Angles
A central element of this experiment is prompt framing. The author stated that the prompt was written specifically to match the camera angles and shot composition depicted in the depth board. In this setup, the depth image serves as the spatial benchmark, and the textual prompt enforces compliance with that geometry.
This represents the extent of the verified workflow from the original post. Full prompt text, reference image dimensions, and specific parameter values were not published in the source and are not filled in here.
Creator Observations on Seedance 2.0 for Animation
In follow-up replies regarding whether Seedance 2.0 remains suited for animation, the author noted that the model "still holds competitive appeal" and is "often utilized in animation workflows." These statements reflect the creator's personal observations rather than an independently verified benchmark.
Realistic expectations should align with the creator's own note: not every cut renders identically to the references, and creators must iteratively compare input combinations against output shots. General multimodal specs or benchmark leaderboard rankings for Seedance 2.0 fall outside the scope of this experiment and are omitted.
Original source
- bunpinku (@bun_pingku) Original Post: What happens when you add depth images to AI animation?