Seedance 2.5 Prompt Guide: Generating Photorealistic Handheld Smartphone GRWM Vlogs
A structured prompt engineering guide for Seedance 2.5 on Higgsfield, using continuous front-camera handheld shake and diegetic room sound to create authentic 3
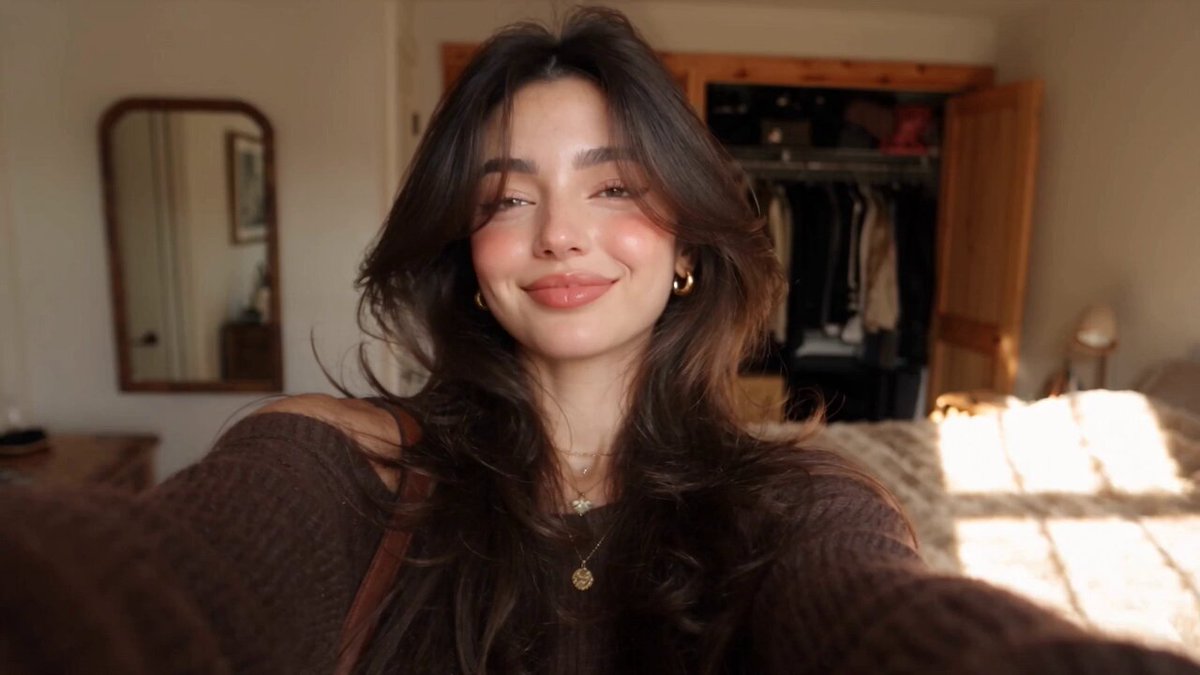
On October 5, 2026, AI video creator Mahira (@MahiraEhan) shared a practical prompt framework and production workflow for generating authentic 30-second Get Ready With Me (GRWM) morning vlogs using ByteDance's multimodal video foundation model Seedance 2.5 hosted on Higgsfield.
Image source: X @MahiraEhan
Rather than relying on the hyper-polished crane pans, studio three-point lighting, and synthetic skin smoothing typical of generative AI videos, this prompting strategy intentionally mimics physical front-camera smartphone optics, arm-length selfie framing, subtle autofocus hunting, and real-world micro-movements to produce grounded short-form lifestyle content.
Handheld Front-Camera Prompting and Anti-Cinematic Directing Rules
The core design principle of this workflow is deliberately eliminating cinematic tropes in favor of everyday mobile camera imperfections.
By explicitly commanding the model to restrict the visual language to an arm-length selfie recording, creators prevent the AI engine from generating third-person camera angles or polished commercial studio lighting.
- One Continuous Handheld Selfie Take: The prompt explicitly enforces a first-person front-camera view held entirely by the subject at arm's length, barring third-person cameras, tripods, and external camera rigs.
- Physical Optical Imperfections: Direct instructions specify realistic front-camera lens distortion, subtle hand tremor, natural arm sway, minor framing shifts, and momentary autofocus hunting as natural artifacts.
- Strict Anti-Filter Aesthetics: The specification rules out beauty filters, artificial skin smoothing, and stylized cinematic color grading, preserving the natural color response and soft window daylight of a smartphone sensor.
- Clean Frame Enforcement: Prompt rules ban embedded subtitles, logos, watermarks, and on-screen graphical elements, delivering clean master footage ready for post-production and platform delivery.
These negative constraints counteract the model's bias toward promotional advertising looks, yielding relatable footage that feels authentic in a mobile social feed.
Scene Progression and Character Consistency: Morning to Departure
The 30-second timeline structures a realistic personal morning routine, progressing from waking up in bed to stepping out the door with timed dialogue and candid micro-actions.
- Waking Up (Bedroom Intro): The subject begins in her bedroom shortly after waking, holding the phone toward herself with a sleepy smile and delivering an opening line.
- Spoken Line: "Okay, I have approximately ten minutes to look like I have my life together."
- Routine Preparation (Outfit & Makeup): Laughing at her own quip, she turns the camera briefly toward her closet before swinging it back to her face, fixing her hair, applying light makeup while looking into the lens, and selecting clothes.
- Candid Micro-Moments: Natural, uncalculated actions—adjusting loose strands of hair, checking a nearby mirror, pausing as if remembering an item, laughing quietly, and glancing off-screen—are scripted into the prompt.
- Departure (Outro & Wrap): Grabbing her bag, she heads toward the bedroom door, addresses the viewer with a concise closing remark, and gently lowers the phone as recording finishes.
- Spoken Line: "Okay, that’s good enough. Let’s go."
A strong initial character anchor—defining a consistent young woman in her early twenties with unchanging facial geometry and hair—ensures identity stability across all 30 seconds.
Diegetic-Only Audio Design: Eliminating Background Music for Realism
Audio engineering in this prompt completely eschews background music (BGM) in favor of diegetic environmental soundscapes native to the scene.
Seedance 2.5 generates synchronized audio within the same single pass as video synthesis. Clearly detailing the acoustic environment in text allows the system to balance speech timing with background foley naturally.
- Bedroom Room Tone: Gentle indoor silence combined with subtle ambient daylight and faint exterior street noise filtered through window glass.
- Foley & Movement Acoustics: Rustling clothing fabric, soft footsteps across the floor, drawers opening and closing, and gentle personal accessories handling.
- Zero Background Music: Eliminating synthetic pads and pop tracks reinforces the feeling of raw, unedited personal smartphone footage rather than a produced commercial.
By pairing natural room tone with authentic mouth sounds and foley, the viewer experiences heightened immersion without the artificiality common in generative media.
Seedance 2.5 Technical Capabilities and Higgsfield Execution Notes
Deploying this workflow effectively on Higgsfield requires understanding the operational capabilities and constraints of Seedance 2.5:
- Native 30-Second Single-Pass Rendering: Unlike Seedance 2.0, which generated 4- to 15-second clips, Seedance 2.5 natively outputs continuous takes up to 30 seconds with synchronous audio in 9:16 vertical mobile aspect ratio.
- Enhanced Prompt Adherence: With roughly 20% higher instruction adherence compared to prior generations, Seedance 2.5 executes sequential dialogue and multi-step camera rotations with significantly lower drift.
- Multimodal Consistency Tools: For ongoing episodic series or virtual creator accounts, creators can combine text prompts with Higgsfield's @Element references or trained Soul IDs to lock facial geometry and styling across separate generations.
- Iterative Testing via Image-to-Video: For creators experimenting with initial concepts, beginning with an Image-to-Video (I2V) pass using a sharp, well-lit reference portrait conserves platform credits while verifying how the model interprets motion and camera directives.
Original source
- Mahira Official X (@MahiraEhan): Seedance 2.5 on Higgsfield GRWM Prompt
- Higgsfield AI Help Center: How to Use Seedance on Higgsfield