OpenAI Releases Official Model Guide for GPT-6 Family: Role Specialization, Caching, and Latency Optimization
OpenAI has published an official practical guide for the GPT-6 model family, detailing role specialization across Astra, Sol, and Luna, reasoning effort control
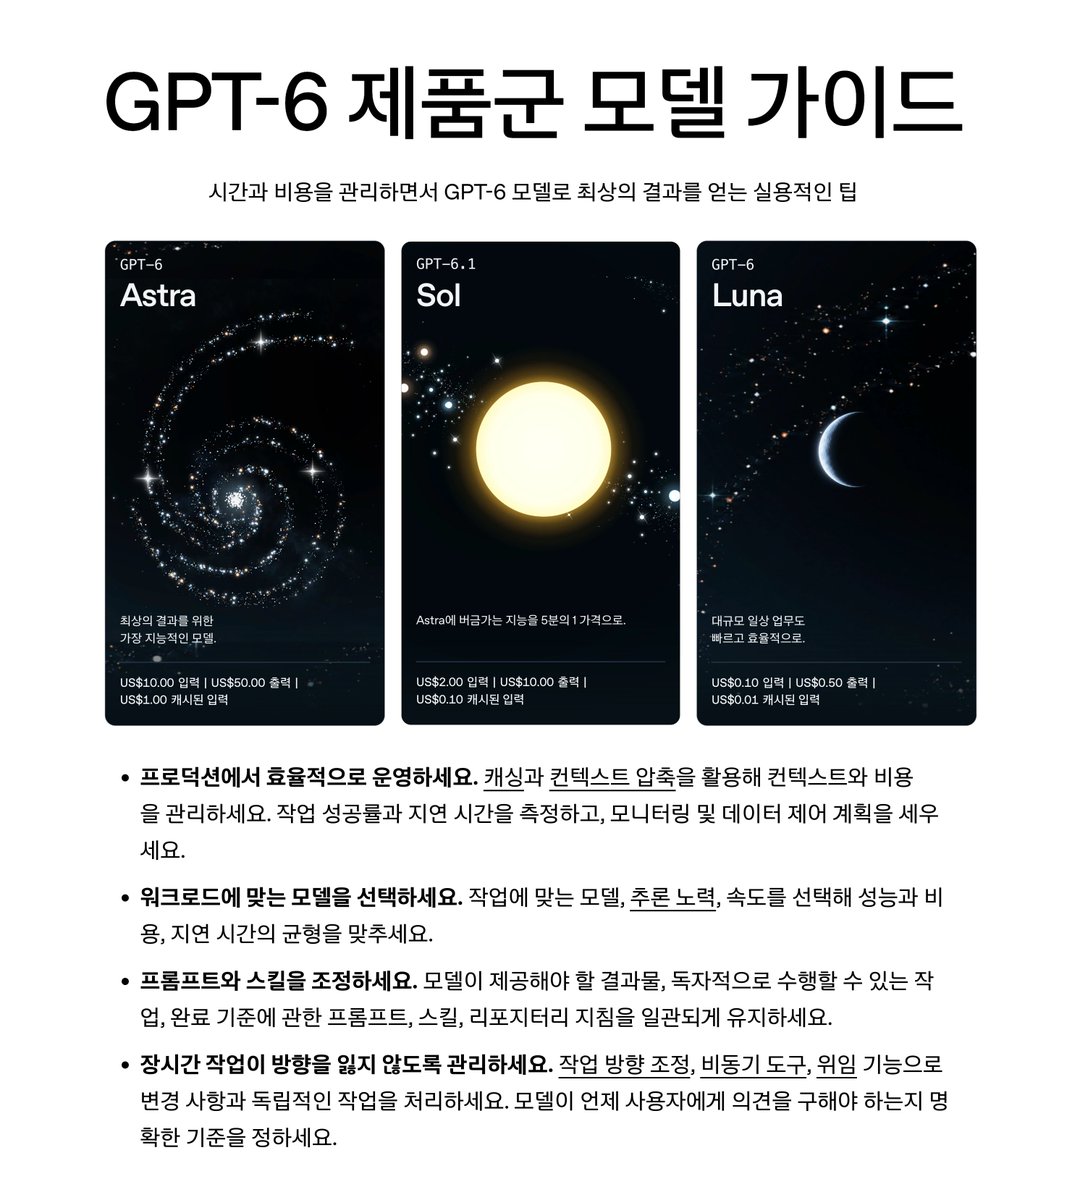
On October 2, 2026, OpenAI officially released an engineering playbook titled "A model guide for the GPT-6 family," designed to guide startup and enterprise engineering teams in deploying its latest foundation models to production. The practical guide outlines actionable techniques for maximizing model accuracy while actively managing API expenses and inference latency.
Image source: OpenAI / @lucas_flatwhite (X)
The newly published guide details structured workload distribution across the lineup—ranging from high-complexity reasoning with Astra, to day-to-day coding and knowledge tasks with Sol, and high-volume routine execution with Luna. It also introduces prompt caching configurations offering up to 95% cost reductions, the configuration_update API payload for preserving prompt prefix caches across mid-session reasoning shifts, latency optimization heuristics, and context compaction mechanisms for multi-day agent operations.
Specializing Workloads Across Astra, Sol, and Luna: Intelligence vs. Cost Trade-offs
Rather than relying on a single monolithic model for all workflows, OpenAI recommends aligning tasks with specific model tiers based on complexity and economic requirements:
- GPT-6 Astra (Complex Reasoning and Maximum Intelligence): Tailored for strategic planning under ambiguity, intricate architectural logic, and domains requiring deep specialized expertise such as law, engineering, and finance. It supports advanced platform capabilities including Computer Use, Structured Outputs, programmatic tool calling, multi-agent orchestration, and Pro mode.
- GPT-6.1 Sol (Coding, Research, and Knowledge Work): Built for full-scope software development, sustained research workflows, cybersecurity, and computer interaction. Providing intelligence close to Astra, it is priced at $2.00 per million input tokens and $10.00 per million output tokens—roughly one-fifth of Astra's operating cost.
- GPT-6 Luna (Repetitive Workloads and Structured Processing): Targeted at predictable, high-volume operational tasks such as invoice item extraction, customer request routing, structured data parsing, and high-throughput summarization. Priced at $0.10 per million input tokens and $0.50 per million output tokens, it offers up to a 100-fold cost reduction compared to Astra.
The guide advises an iterative optimization methodology: teams should first achieve their target accuracy benchmarks using the highest-capability model (Astra), then progressively downscale and distill validated prompts into lighter models such as Sol or Luna against a curated evaluation dataset.
Up to 95% Prompt Caching Discounts and Cache Retention via configuration_update
Prompt caching represents a primary lever for curtailing both financial expenditure and request overhead:
- Up to 95% Cache Discount: When prompt prefixes match cached segments, cached input token pricing is discounted by up to 95% depending on the model (e.g., $1.00 vs. $10.00 per million input tokens on Astra, and $0.10 vs. $2.00 on Sol).
- Reasoning Effort and Cache Invalidation Risks: Developers can tune reasoning intensity across distinct levels (
none,minimal,low,medium,high,max). However, modifying request-level parameters such asreasoning.effort(in the Responses API) orreasoning_effort(in Chat Completions) mid-conversation alters the prompt prefix hash, invalidating the cached context. - Preserving Caches with
configuration_update: OpenAI highlights theconfiguration_updateinput entry for multi-turn sessions. This parameter allows systems to escalate reasoning effort for difficult problem phases and lower it for routine follow-ups without rewriting or breaking the original prompt prefix cache.
Latency Heuristics: The '50% Output Token Reduction' Rule and Context Compaction
The engineering guide also articulates proven latency optimization rules gathered from production deployments:
- The Primacy of Output Token Generation: In LLM inference pipelines, token generation constitutes the primary latency bottleneck. As a general rule of thumb, reducing output tokens by 50% cuts overall latency by approximately 50%. In contrast, halving prompt (input) length yields only a modest 1% to 5% latency improvement. Optimization efforts should therefore focus on tightening system output constraints rather than aggressively truncating prompts.
- Predicted Outputs Acceleration: For tasks where output text is largely predictable—such as localized code refactoring or template transformation—enabling Predicted Outputs significantly reduces token generation cycles.
- Context Compaction for Long-Horizon Workflows: Autonomous workflows running over hours or days risk encountering context window limits and compounded response delays. OpenAI recommends periodic context compaction, condensing intermediate histories and tool execution trails into structured status checkpoints to maintain responsiveness and state coherence.
Enterprise Implementations and Production Readiness Checklist
The guide documents concrete production outcomes achieved by early enterprise adopters leveraging the GPT-6 architecture:
- InVideo: Integrated GPT-6 Astra into its video generation and editing pipeline, resulting in an approximate threefold increase in automated color correction and grading success rates.
- Harvey, Cognition, and Hex: Deployed across legal document analysis (Harvey), autonomous software engineering agents (Cognition), and interactive data analytics (Hex), utilizing Astra's deep reasoning and structured tool coordination to elevate workflow reliability.
Before advancing LLM workflows to production, OpenAI emphasizes verifying four core criteria: baseline evaluation metric definitions, automated fallback routing paths, compaction interval thresholds for long sessions, and simulated cost projections across varying reasoning effort tiers.
Sources
- OpenAI Official Engineering Guide: A model guide for the GPT-6 family
- OpenAI API Documentation: Latest Model Guide & Latency Optimization
- Lucas (@lucas_flatwhite) on X: 2026-10-05 GPT-6 Family Model Guide Commentary