How to Access Free Uncensored GLM 5.3 Flash: Shared 13M TPM and Up to 360 TPS on Experiential Labs
A practical guide to accessing the free uncensored GLM 5.3 Flash model on Experiential Labs, featuring a shared 13M TPM capacity, peak speeds up to 360 TPS, hyb
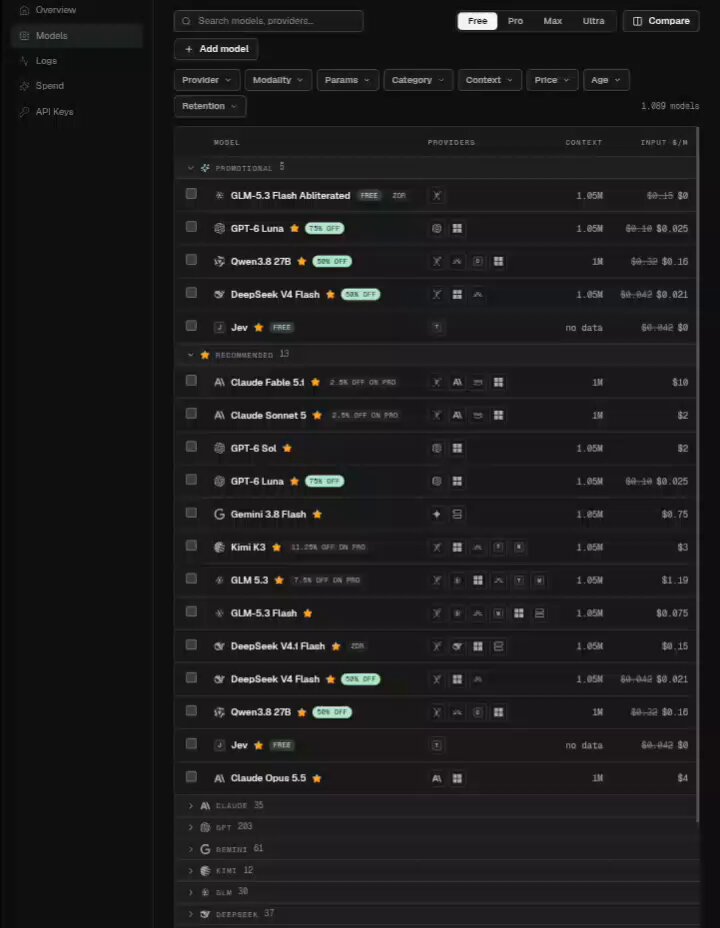
Tech creator Nexx (@nex_ify) on X shared details about a free endpoint providing access to an uncensored variant of GLM 5.3 Flash on the Experiential Labs platform. The promotional endpoint offers a shared community pool capacity of approximately 13 million tokens per minute (TPM) and peak throughput reaching up to 360 tokens per second (TPS).
Image source: Nexx (@nex_ify) / Experiential Labs
320B Hybrid MoE Architecture and Weight-Level Uncensoring
GLM 5.3 Flash is a foundation model developed by Z.ai (Zhipu AI) featuring a 320 billion total parameter architecture with roughly 18 billion active parameters per token. It incorporates a hybrid attention mechanism combining KDA linear attention with DeepSeek-style sparse Multi-Head Latent Attention (MLA).
- Native 1M Context Window: Directly supports extensive context lengths up to 1,048,576 tokens.
- Multimodal Vision and Reasoning: Includes native multimodal vision capabilities for image inputs (
image_url), alongside native support for tool calling, structured outputs, and multistep reasoning. - Permanent Weight-Level Abliteration: The uncensored variant (from the dealignai and Solstice-AI lineage) removes refusal behavior directly from the model weights rather than relying on prompt jailbreaks, LoRA adapters, or runtime hooks. This addresses aggressive over-refusal on benign queries, code auditing, and copyright-flagged research tasks.
Three Steps to Access on Experiential Labs
Accessing the uncensored GLM 5.3 Flash model on Experiential Labs requires only three quick steps:
- Navigate to the Model Hub: Open your browser and go to the Experiential Labs model directory at
https://platform.experientiallabs.ai/models. - Sign Up: Create an account or sign in with your email credentials.
- Select Model: Choose GLM 5.3 Flash (Uncensored) from the model selector to begin executing queries and running evaluations.
The web playground does not require entering payment credentials before testing the available models.
Shared Quota (13M TPM), Speed Profile, and Usage Considerations
Because this free tier operates as a shared promotional resource, developers and researchers should keep several operational constraints in mind:
- Shared Throughput and Performance: With an aggregate ~13M TPM shared pool and Multi-Token Prediction (MTP) speculative decoding, peak output rates can reach up to ~360 TPS. However, latency and queue times may fluctuate during high-concurrency periods.
- Availability Window: As a promotional community offering, access terms, model availability, or rate caps may change or terminate without advance notice.
- Responsibility for Uncensored Output: Because safety guardrails have been abliterated at the weight level, the model will comply with requests that standard aligned checkpoints reject. It is primarily intended for controlled security research, penetration testing, malware analysis triage, and alignment evaluation. Users remain responsible for deployment compliance and ethical usage.
- Distinction from Official Commercial APIs: Official Z.ai commercial API tiers charge standard rates ($0.15 per 1M input tokens and $0.50 per 1M output tokens). Teams requiring dedicated SLAs and enterprise uptime guarantees should rely on commercial endpoints, while reserving this free instance for rapid prototyping and adversarial testing.
Original source
- Original post by Nexx (@nex_ify): Someone is giving away FREE GLM 5.3 Flash (uncensored)
- Experiential Labs Model Platform: Experiential Labs Models Hub