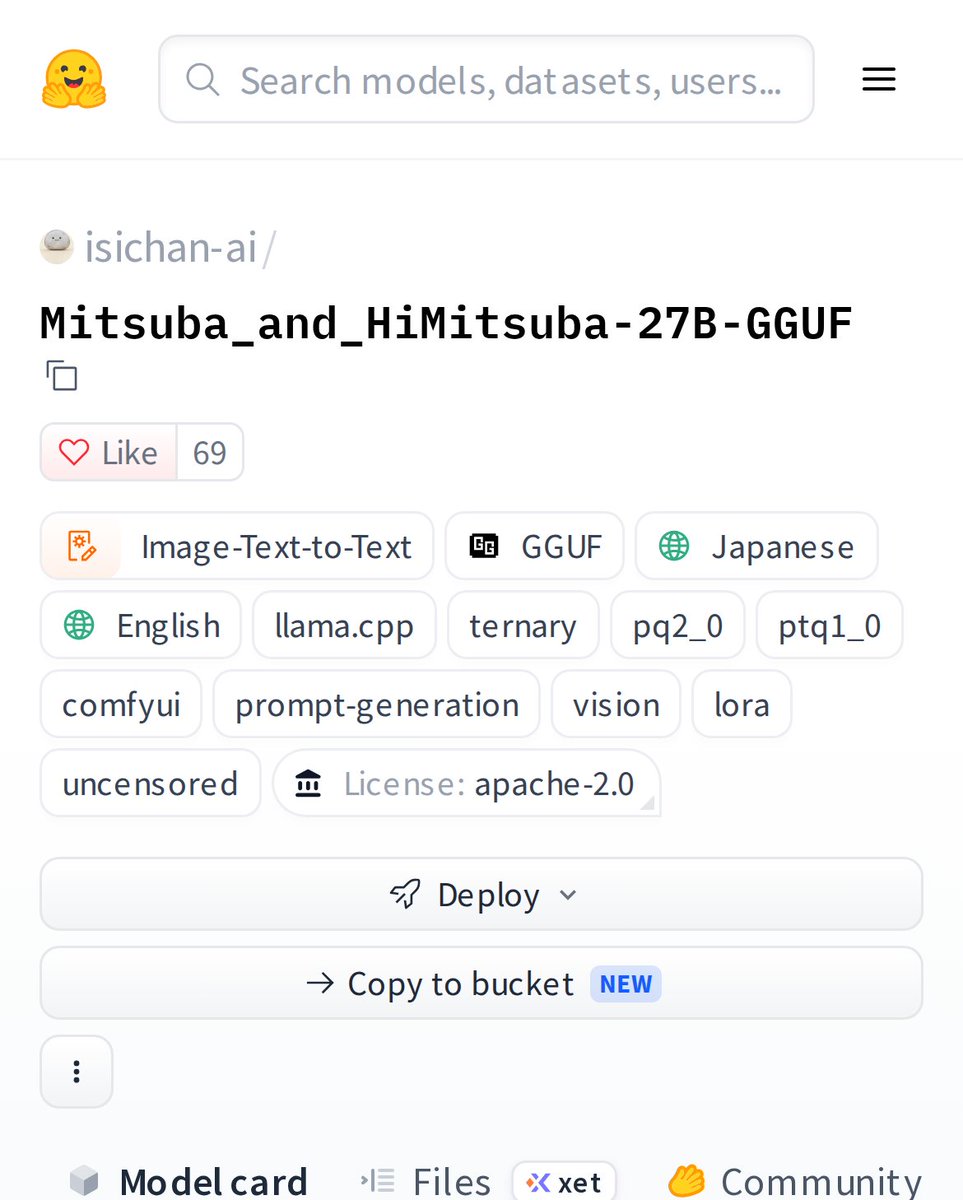
Mitsuba & HiMitsuba 27B GGUF: A 1.58-Bit Vision-Language Model for ComfyUI on 16GB GPUs
Mitsuba and its uncensored HiMitsuba LoRA compress Qwen3.8-27B into a 7.3GB 1.58-bit VLM, enabling fast local image analysis and prompt generation for ComfyUI o
TAU-HOME.COM stories tagged VLM.
Mitsuba and its uncensored HiMitsuba LoRA compress Qwen3.8-27B into a 7.3GB 1.58-bit VLM, enabling fast local image analysis and prompt generation for ComfyUI o
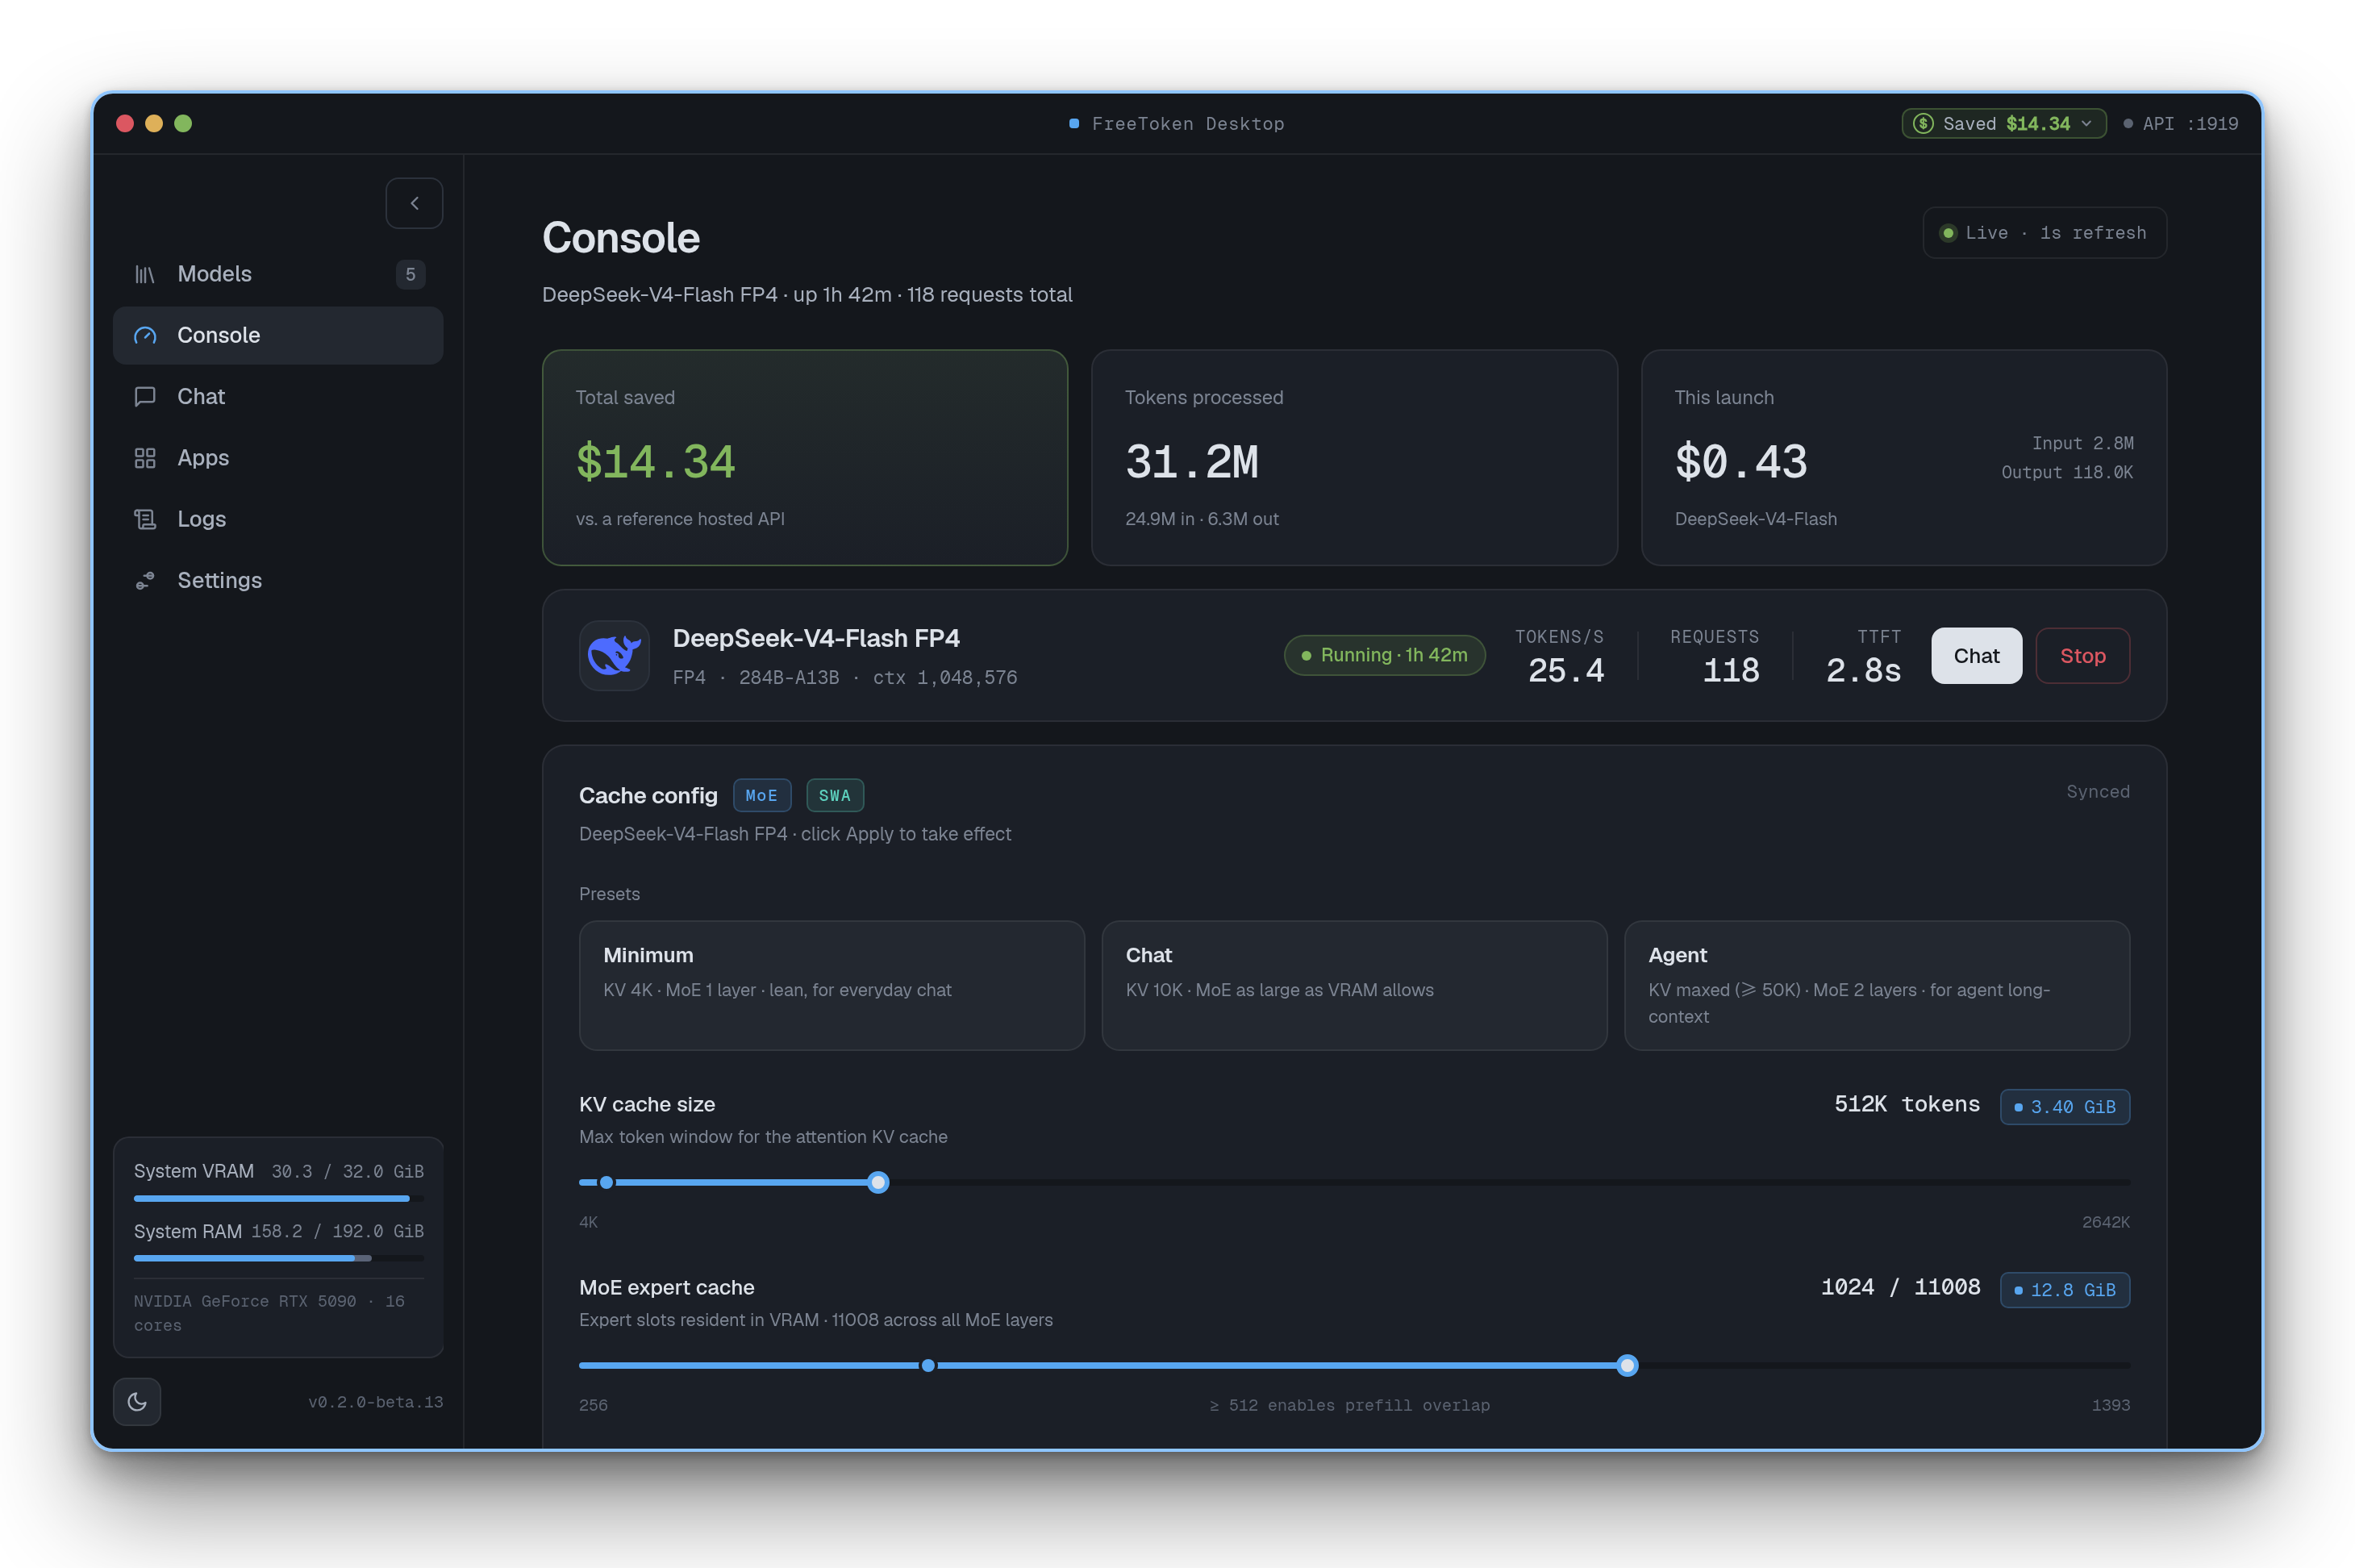
FreeVideo enables on-device video and asset generation on consumer PCs. Paired with FreeToken, it automates the pipeline from storyline planning to video render
Yohei Nakajima has open-sourced glance-vlm speedlab, a local VLM harness that skips token generation to run live webcam detectors in 160ms via single forward pa
Apple has released LensVLM-9B on Hugging Face. Fine-tuned on Qwen3.5-9B, the VLM scans compressed document pages to cut tokens and selectively expands relevant
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285