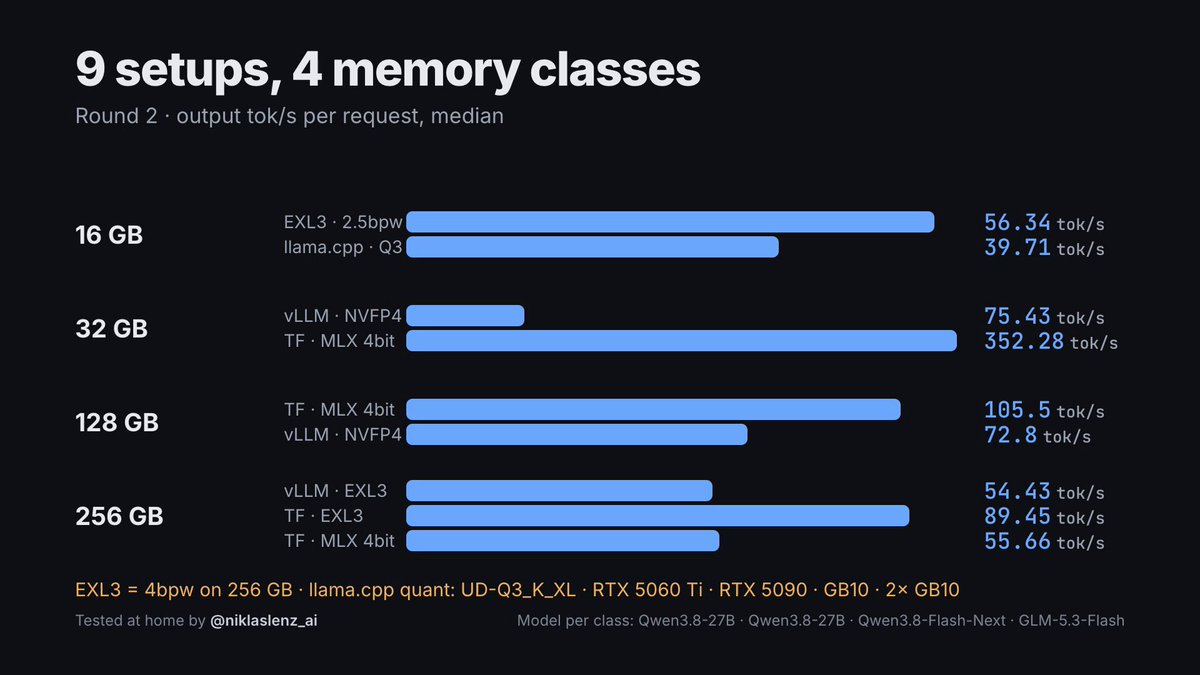
Local AI Runtime Benchmarks: Comparing exllamav3, llama.cpp, vLLM, and TensorFold Across 16GB to 256GB Memory Classes
Empirical benchmark results comparing local LLM inference speeds (tok/s) and Time to First Token (TTFT) across RTX 5060 Ti (16GB), RTX 5090 (32GB), and GB10 (12