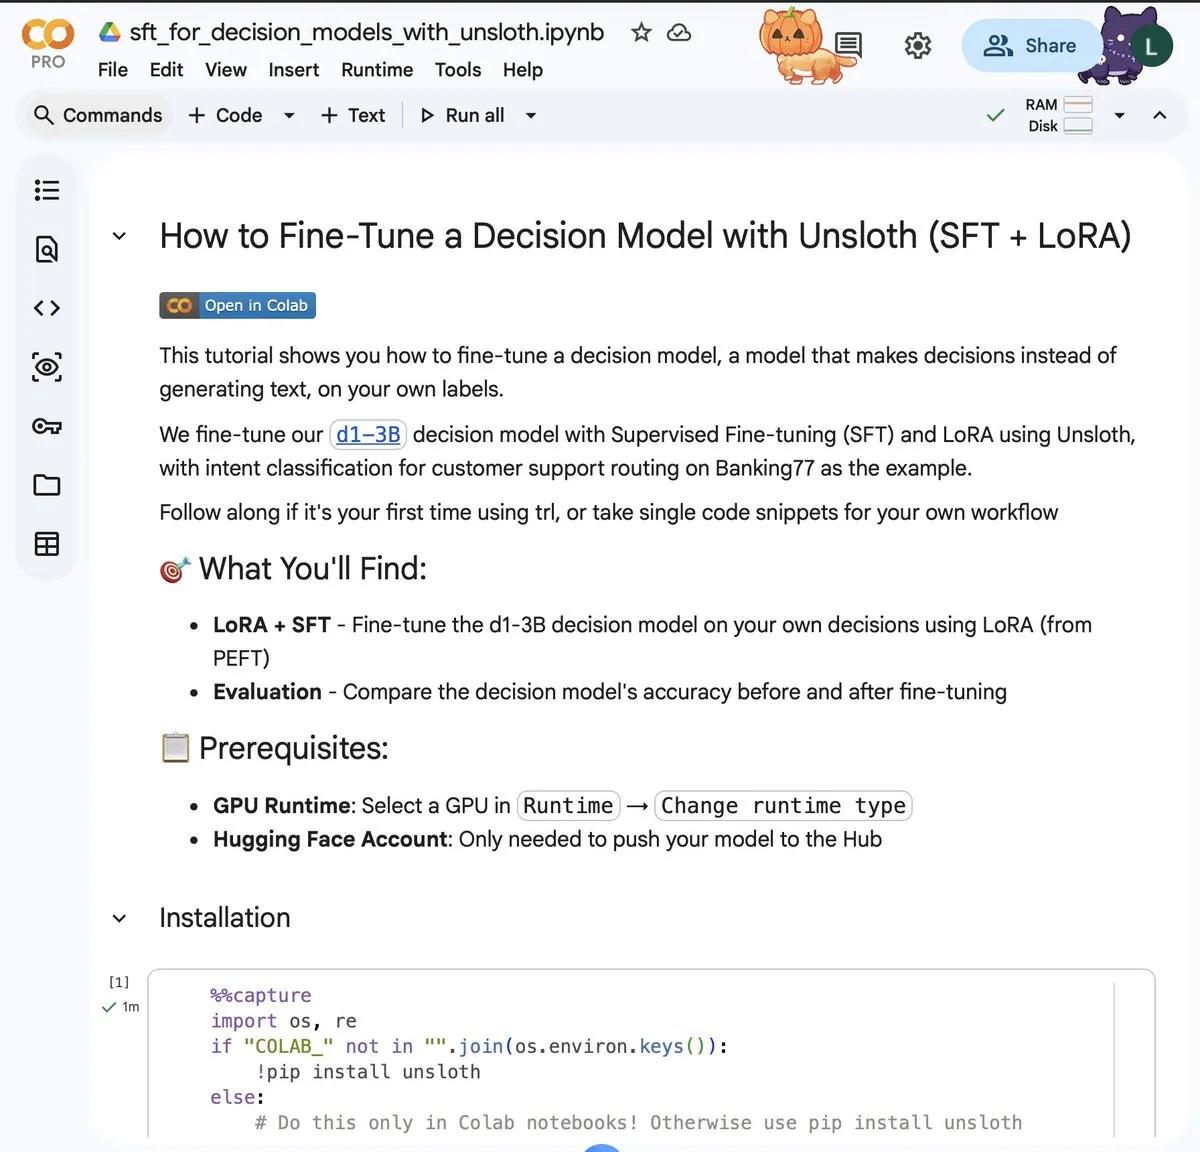
How to Fine-Tune the d1-3B Decision Model on Custom Data: Hands-on with Unsloth and TRL
A complete practical guide to fine-tuning the d1-3B decision model in under 30 minutes on a free-tier GPU using Unsloth and Hugging Face TRL, covering case-base
TAU-HOME.COM stories tagged FineTuning.
A complete practical guide to fine-tuning the d1-3B decision model in under 30 minutes on a free-tier GPU using Unsloth and Hugging Face TRL, covering case-base
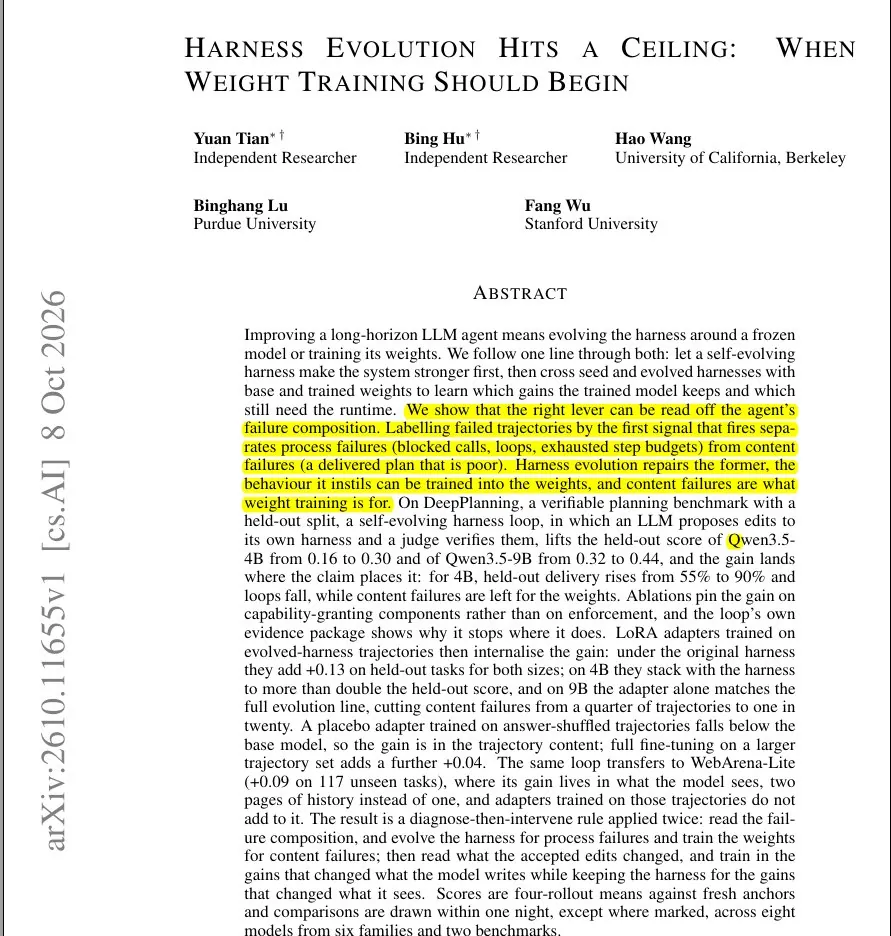
A summarizer presents this as a Stanford study separating agent failures into process failures and content failures, and distinguishing harness evolution from L
Together AI released tev1-4B-experimental, an open-source Jev-style classifier on Qwen3.5 4B fine-tuned for $17. Weights, data recipes, and serverless hosting a
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285