Train LLM from Scratch with PyTorch
A learning-focused repository that walks through implementing a transformer architecture from scratch using PyTorch, covering everything from dataset preparatio
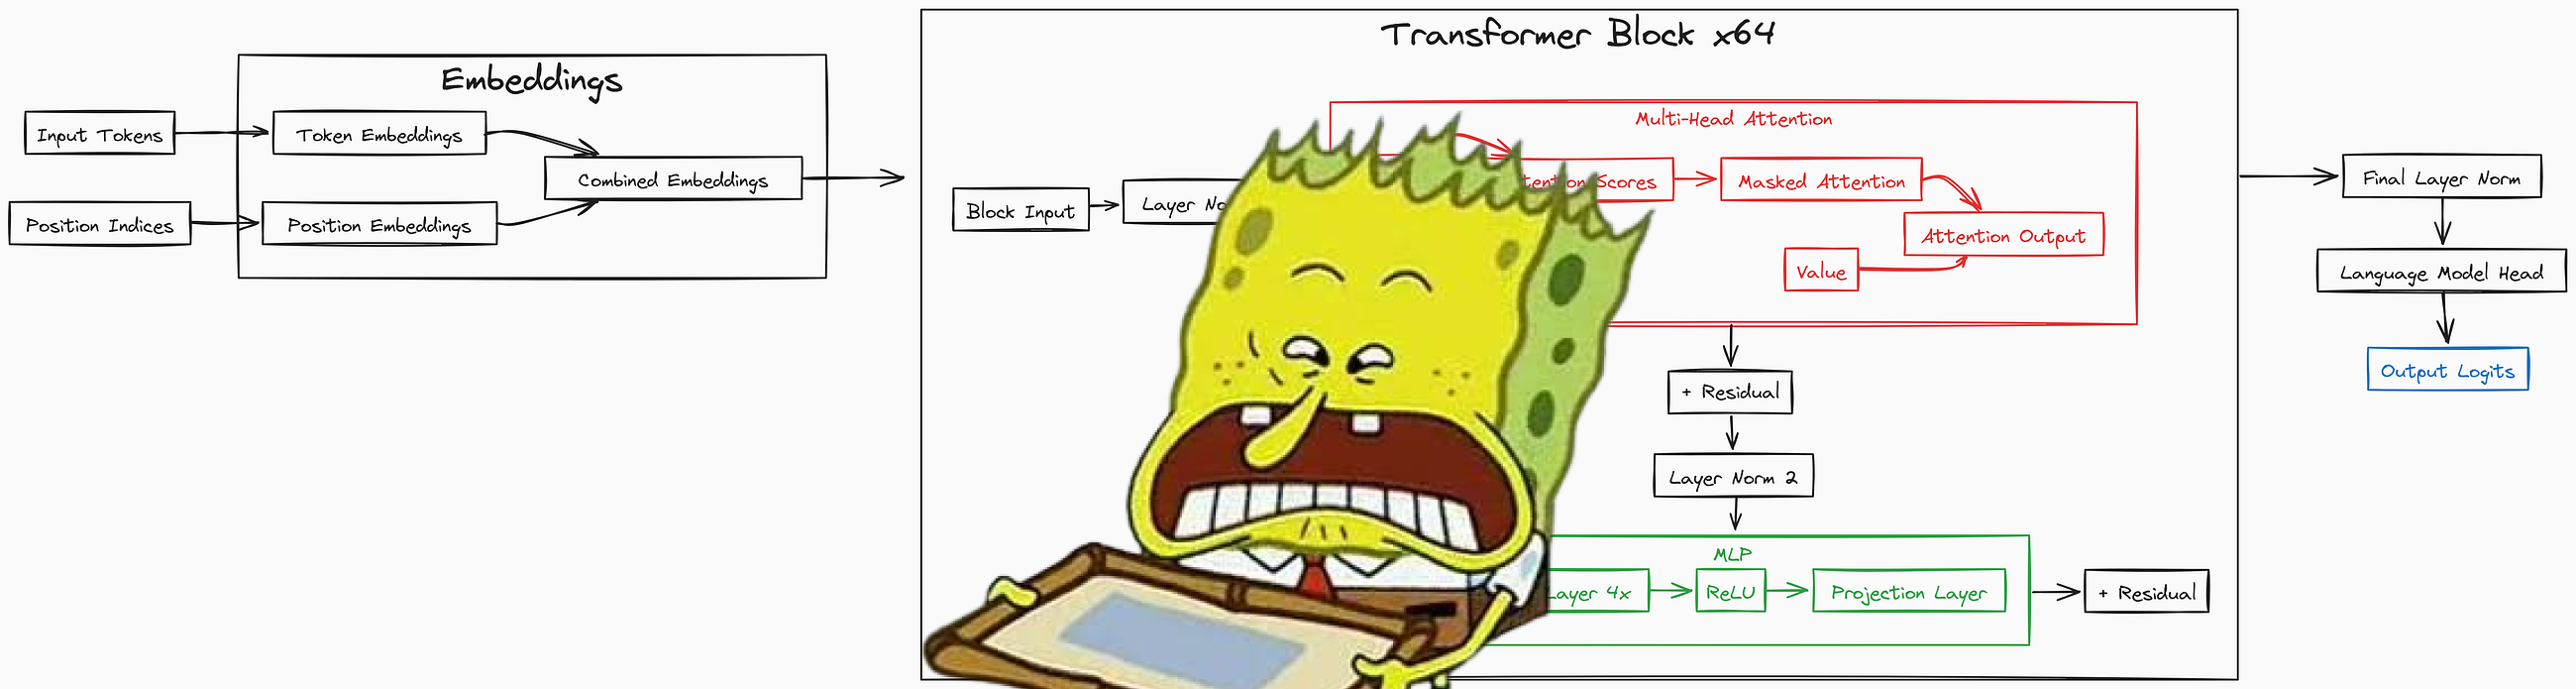
Image source: https://github.com/FareedKhan-dev/train-llm-from-scratch
The 'FareedKhan-dev/train-llm-from-scratch' repository provides a step-by-step guide for learning the principles of LLM training by building a transformer model from scratch using only pure PyTorch, avoiding high-level library abstractions.
This repository is ideal for developers aiming to grasp the fundamental mechanics of large language models. It provides hands-on examples that walk through designing and training a model without relying on complex, pre-built frameworks.
Implementing Transformers with Pure PyTorch
Based on the "Attention is All You Need" paper, this repository demonstrates how to implement the core components of a transformer architecture using PyTorch.
- Architectural Design: It implements core structures like Multi-head Attention and MLP blocks directly at the code level.
- Minimal Dependencies: By avoiding high-level libraries such as
trl,peft, ortransformers, it allows users to understand the learning process through direct implementation using only PyTorch's fundamental features.
From Data Pipeline to Inference
The repository covers not just model training but also the essential pipeline for preparing data.
- Data Processing: It includes scripts to download, preprocess, and tokenize (using
tiktoken) 'The Pile' dataset, and save it in HDF5 format for efficient training. - Step-by-step Guide: It covers the entire process from data preprocessing to model training and inference.
This repository is focused on learning and understanding principles, so users should note that they may need to build optimizations or complex distributed training environments themselves for production use cases.