An X Post on 'The End of Harness Engineering': Auto-Evolution Loops and Eval-Driven Development
An overview of AnnatarXBT's account of 'The End of Harness Engineering,' describing a 4B model, eight candidate edits, held-out questions, and a shift toward sc
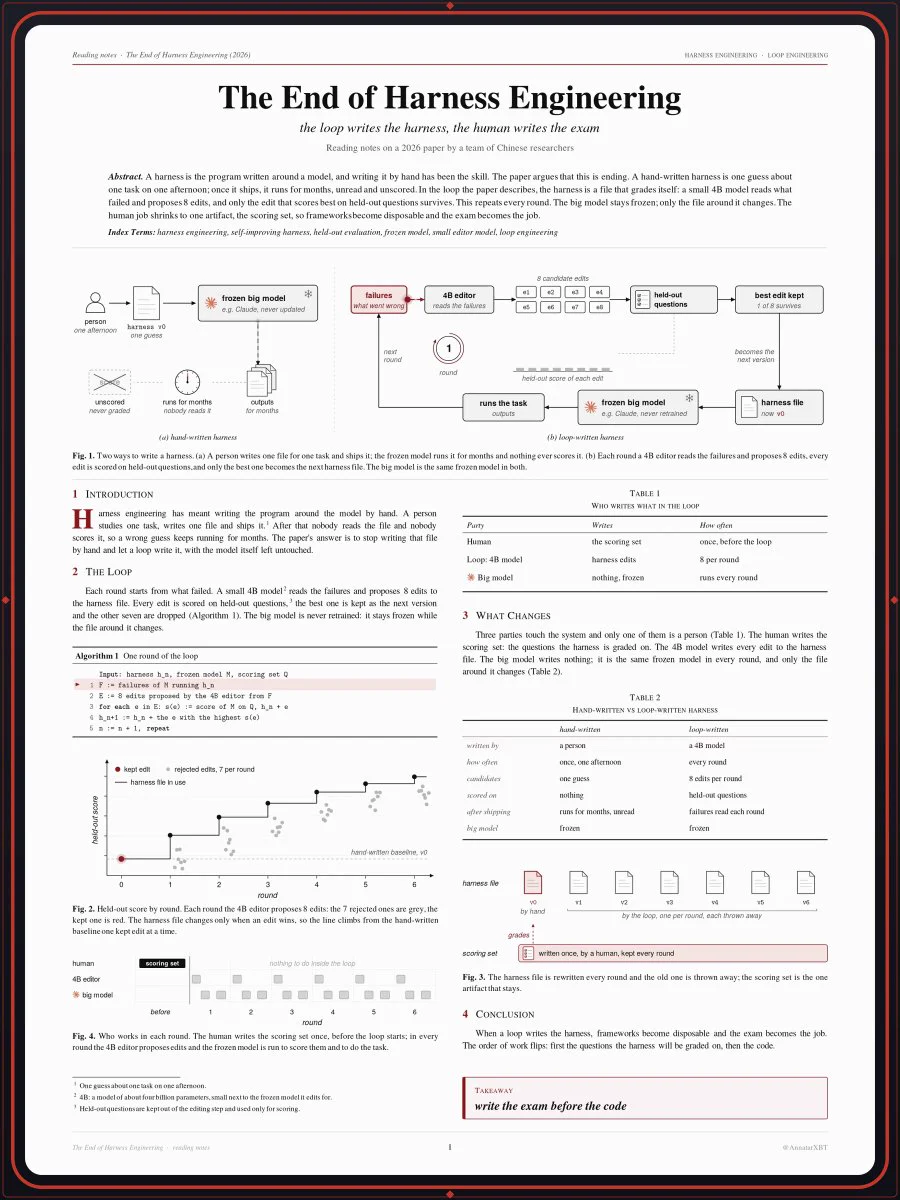
In an October 31, 2026 X post, AnnatarXBT described a paper titled 'The End of Harness Engineering' and attributed it to Chinese researchers. According to the post, its central claim is that hand-writing the program around a model is becoming obsolete as a skill.
Image source: AnnatarXBT / X (@AnnatarXBT)
Illustration summarizing the AnnatarXBT X post discussed below
Source post discussed: AnnatarXBT / X (@AnnatarXBT)
Limits of Manual Harness Design and the New Research Hypothesis
AnnatarXBT's post contrasts a person-written harness—described as one guess for one task that may run for months unread and unscored—with a loop-written file that grades itself.
The post's central claim is that hand-writing the program around a model is becoming obsolete as a skill. It describes a loop that reads what failed and uses held-out questions to select edits to the harness.
The 4B Model and Held-Out Eval Auto-Evolution Loop
According to AnnatarXBT's post, a small 4B model operates around a frozen larger model:
- Failure Analysis and Edits: The 4B model reads what failed and proposes eight edits.
- Held-Out Eval Scoring: The edits are scored on held-out questions.
- Survival of the Best Edit: Only the edit with the best score survives.
The larger model remains frozen while each round rewrites the file around it. The post characterizes frameworks as disposable.
Scoring Sets as the Human's Main Artifact
AnnatarXBT's post says the human job shrinks to the scoring set: the questions used to grade the harness. It summarizes the proposed workflow as writing the exam before the code.
In a reply, @Rachel_hkz suggested separating unseen held-out cases to limit overfitting to scoring-set bias. Replies by @travis649411644 raised validation, regression, and rollback as concerns. These are commenters' concerns, not demonstrated findings in the supplied evidence.
Sources
- AnnatarXBT on X: Post about 'The End of Harness Engineering'