155MB Character LoRA for MiniMax H3: Zero-Reference Local Video Generation
Playtime-AI released a 155MB character LoRA for the 33B open-weight MiniMax H3 model, enabling consistent video generation directly from text prompts without re
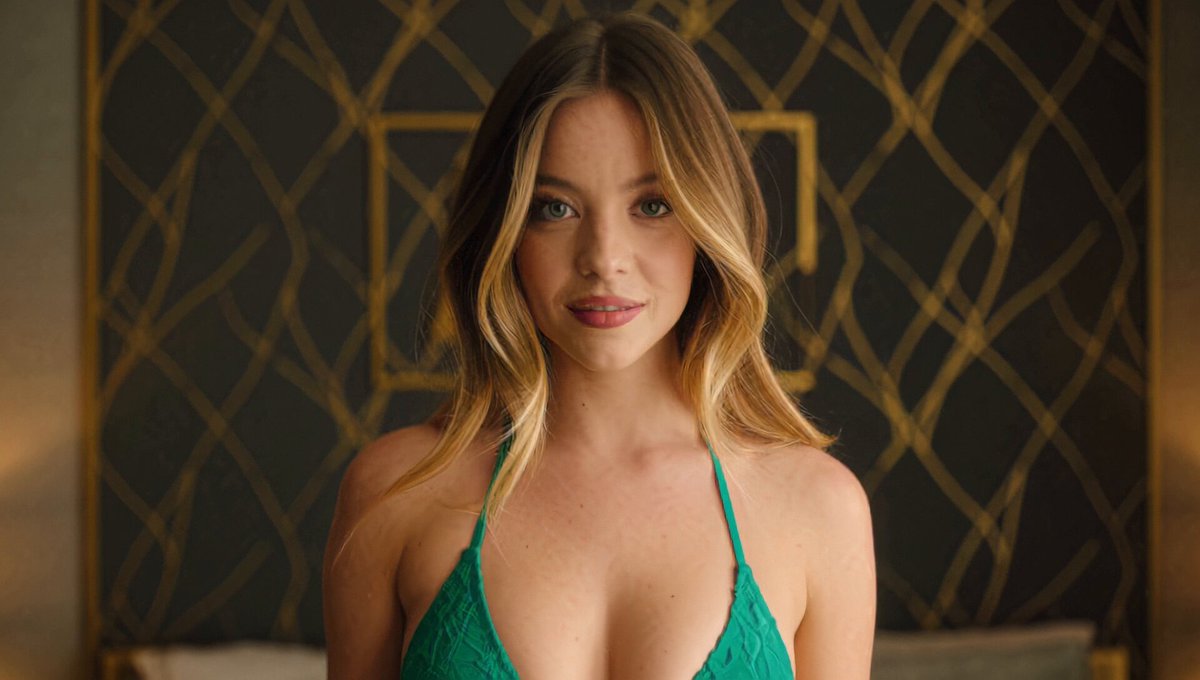
Maintaining consistent facial identity and character features across generated video frames has long been one of the most persistent bottlenecks in open-source generative video. Recently, open-source community developer Playtime-AI released 'Minimax_H3-Sydney_Sweeney' on Hugging Face—a lightweight 155MB character LoRA weight designed specifically for MiniMax H3, the 33-billion (33B) parameter open-weight video and audio foundation model.
Image source: X / @0x0SojalSec / Playtime-AI
Conventional image-to-video (I2V) and multi-reference video generation (Ref2V) pipelines typically require creators to supply initial keyframes or multiple angle shots of a subject to preserve visual likeness. In contrast, this LoRA bypasses reference image inputs entirely. By specifying the subject's name (Sydney Sweeney) directly within a text prompt, it hooks into the base model's underlying rendering pipeline to generate high-resolution video clips locally and completely offline.
Architecture: Combining a 155MB LoRA with a 33B Multimodal Foundation Model
MiniMax H3 is a 33-billion parameter open-weight multimodal model that processes text, images, video, and audio contexts to generate up to 15 seconds of 2K video alongside natively synchronized stereo sound. The foundation model handles complex temporal dynamics, expressions, camera motions, and cloth physics, as well as background acoustic atmospheres and voice tracks in a unified generation pass.
The checkpoint published by Playtime-AI packages low-rank parameter updates into a compact 155MB .safetensors file.
- Base Weights Preservation: Rather than modifying or fine-tuning the full 33B parameter foundation weights—which occupy roughly 32GB under INT8 quantization—the LoRA dynamically injects low-rank adaptation matrices into key attention projection layers.
- Zero-Reference Identity Synthesis: Instead of relying on image conditioning modules, identity-specific tokens in the text prompt map directly to the learned facial geometry vectors, preserving recognizable likeness without requiring input image assets.
- Offline Native Rendering: The pipeline executes fully on local hardware, requiring no external cloud API connectivity, remote subscription tiers, or hosted moderation gates.
Local Runtime Requirements and Pipeline Configuration
Distributed via Hugging Face, the LoRA checkpoint is structured for straightforward integration into local MiniMax H3 inference environments.
- Pipeline Loading: Within an open-source MiniMax H3 runtime environment (such as Python scripts or compatible community interfaces), creators attach the checkpoint path and set the target adapter strength via the pipeline's
lorasconfiguration parameter. - VRAM Hardware Constraints: While the LoRA itself is only 155MB, running the underlying 33B foundation model demands substantial GPU memory. Local execution generally requires at least 24GB to 32GB of VRAM, making INT8 quantization practically essential on consumer-grade hardware.
- Prompt Direction: Creators direct scenes using natural descriptive prompts, defining lighting, background settings, camera choreography, and physical action alongside the subject identifier without complex custom control tokens.
Practical Limitations and Ethical Considerations
While this release demonstrates that a 155MB adapter can enforce recognizable character likeness on a 33B video foundation model, several technical trade-offs and operational caveats warrant attention.
- Drift Under Radical Angles and Lighting: Because the model is not anchored to a static reference image, severe camera rotations, rapid motions, or high-contrast lighting shifts can cause subtle facial drift or geometric distortion across prolonged sequences.
- Base Model Memory Overhead: The lightweight footprint of the LoRA adapter does not diminish the memory overhead of the 33B base model, maintaining a high hardware entry barrier for systems without high-end or multi-GPU setups.
- Identity Rights and Deepfake Safeguards: Because the checkpoint reproduces the recognizable likeness of a real-world public figure, it carries significant risks of misuse regarding unauthorized synthetic media and non-consensual deepfakes. Responsible deployment aligned with applicable legal and ethical guidelines remains critical.