NVIDIA Releases Nemotron 3.5 Transcribe 30B MoE Speech Model
NVIDIA released Nemotron 3.5 Transcribe, an open-weight speech model with about 34B total and 4.3B active parameters supporting transcription in 40 languages an
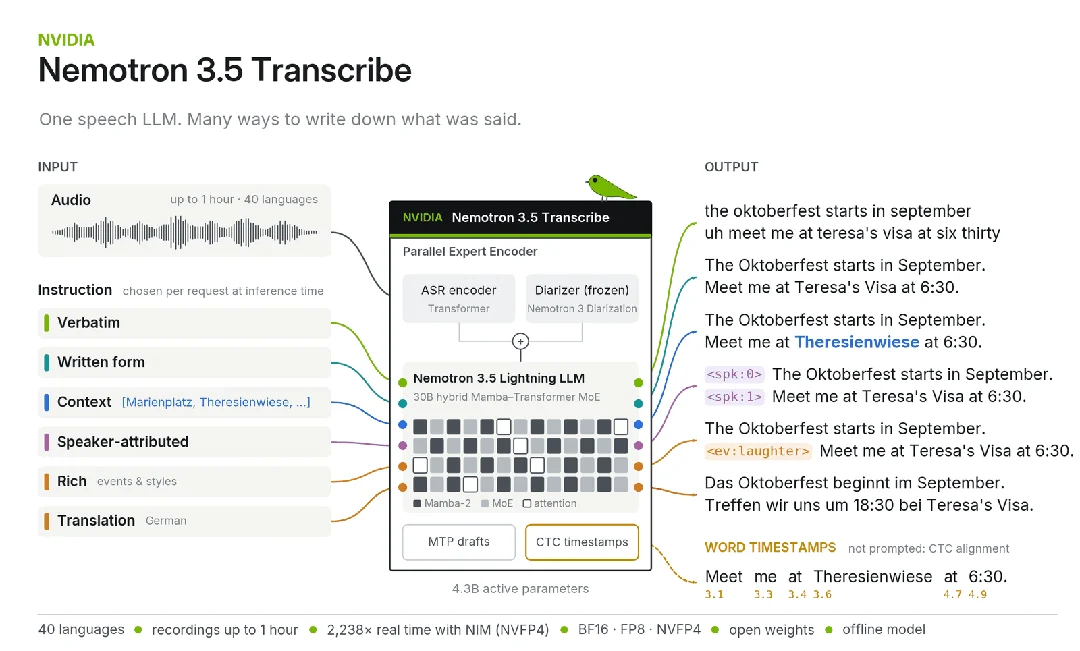
On October 28, 2026, NVIDIA officially announced Nemotron 3.5 Transcribe, an open-weight speech model built around a 30B Mixture-of-Experts (MoE) language backbone, with approximately 34B total and 4.3B active parameters including the audio encoder.
Image source: NVIDIA / Hugging Face official model repository
The model checkpoint, open datasets, and fine-tuning recipes have been published on Hugging Face, unifying multilingual speech transcription, speaker diarization, translation, and audio understanding into a single promptable checkpoint.
Unifying 40-Language Transcription, Speaker Diarization, and Audio Understanding
Nemotron 3.5 Transcribe leverages a Mixture-of-Experts architecture. Its language backbone has approximately 30 billion parameters; the full speech model has about 34 billion, with roughly 4.3 billion active during inference.
Rather than stitching together disparate modules for speech-to-text, speaker attribution, translation, and text sanitization, the checkpoint handles these functions concurrently through natural language prompting.
- Unified Multitask Execution: Supports transcription across 40 languages, speaker labeling (identifying distinct speakers in overlapping audio), translation into languages such as Spanish and Japanese, and contextual prompting.
- Audio Understanding and PII Redaction: Capable of detecting and redacting personally identifiable information (PII) directly from audio recordings according to user prompts.
- Overlapping Speech Handling: Tracks conversational turns in multi-speaker environments, such as meetings where participants speak simultaneously.
Open ASR Leaderboard Rankings and 4B Active Parameter Benchmarks
According to benchmark results published by NVIDIA, Nemotron 3.5 Transcribe achieved the #1 ranking among open-weight models on the Hugging Face Open ASR English leaderboard. The leaderboard screenshot in NVIDIA's Hugging Face blog reports 5.33% average Word Error Rate (WER); NVIDIA's research page separately reports 4.71% across nine public test sets.
The system also secured the top position in VoiceArena's 14-system diarization and ASR comparison, as well as David AI's multilingual diarization benchmark.
On Artificial Analysis non-streaming benchmarks, NVIDIA's self-reported test numbers indicate a 2.81% Word Error Rate using ~4B active parameters. In comparison, Voxtral Small recorded a 2.77% WER while utilizing 24B active parameters. This configuration delivers comparable transcription accuracy while requiring roughly one-sixth of the active parameter footprint.
Fine-Tuning Workflows and Operational Scope
Alongside model weights, NVIDIA released Granary v2 open speech data and NeMo Speech fine-tuning tools. Ecosystem integrations with inference engines including vLLM and SGLang were also outlined.
In a medical ASR case study reported by NVIDIA, domain-specific fine-tuning reduced the word error rate by 45.8% relative to the best prompting approach on held-out speakers.
Deployments should account for specific operational parameters:
- Offline Processing Only: The architecture is designed for non-streaming batch transcription of recorded audio rather than low-latency real-time streams.
- Evaluated File Duration: Official evaluations and benchmark validations were conducted on recordings up to one hour in length.
- Reported Metrics: Comparative accuracy figures outside the public leaderboard represent NVIDIA's self-reported benchmark tests.
Sources
- NVIDIA AI Official X (@NVIDIAAI): Nemotron 3.5 Transcribe Announcement
- NVIDIA Research: Nemotron 3.5 Transcribe Official Research Page
- NVIDIA Research Authors on Hugging Face: Nemotron 3.5 Transcribe and Granary v2
- Hugging Face Model Repository: NVIDIA-Nemotron-3.5-Transcribe-30B-A4B
- Hugging Face Open ASR Leaderboard: Open ASR English Leaderboard