400,000 Classical Chinese Poems as an API: Open-Source chinese-poetry-api
An open-source Go-based API serving roughly 400,000 classical Chinese poems — Tang poetry, Song lyrics, Yuan songs, the Book of Odes, and the Songs of Chu — ove
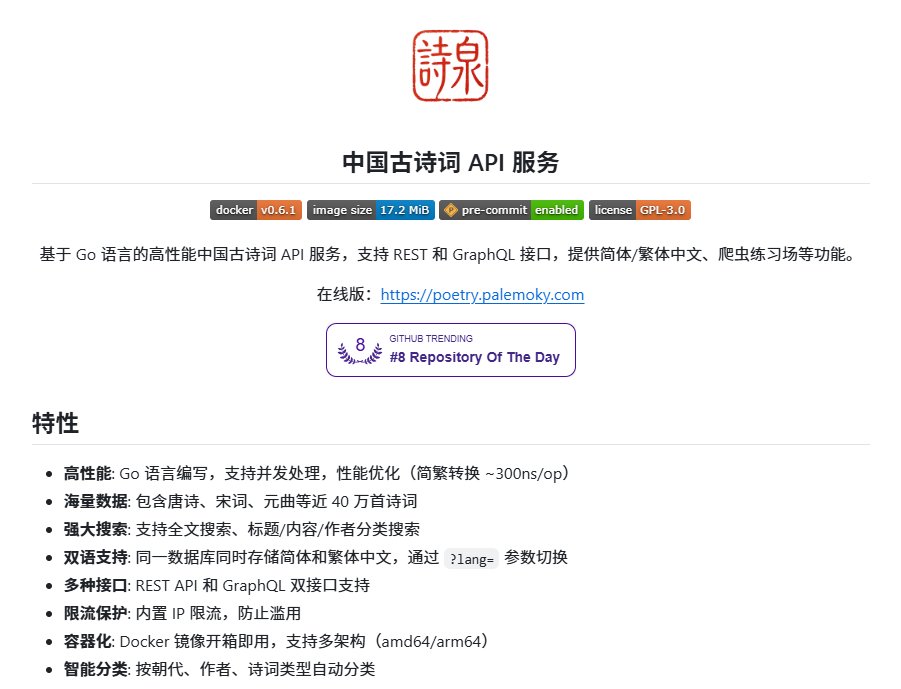
X user Gk (@0xGky) introduced the open-source project chinese-poetry-api on October 8, 2026: a package bundling roughly 400,000 classical Chinese poems into ready-to-call interfaces, so developers can fetch poem texts without scraping, cleaning, or building their own database.
Image source: @0xGky (X)
According to the post, the collection spans Tang-dynasty poetry, Song-dynasty lyrics, and Yuan-dynasty songs, alongside older classics such as the Book of Odes (Shijing) and the Songs of Chu (Chuci). In short, a cross-genre anthology of Chinese classical literature gathered into a single queryable dataset.
What it offers
The advertised feature set is lookup-oriented and simple: browse by dynasty, author, and genre, full-text search, a random-poem endpoint, and simplified/traditional Chinese conversion. That makes it an easy fit for small educational tools or chatbots that need "a classical poem on demand."
Technically, the project is described as written in Go, exposing both REST and GraphQL interfaces, and runnable in one step via Docker for self-hosting. Note the evidence boundary: the only verified material is the post itself with its attached image. Repository URL, actual endpoint specifications, and license terms could not be confirmed from this evidence alone, so no install commands are given here.
Who it suits
It is a useful starting point for developers building study apps, reading tools, or experimental bots around classical Chinese texts — skipping the work of assembling a 400,000-item corpus and starting directly from the query layer.
Two caveats apply. Self-hosters should check indexing and memory requirements for roughly 400,000 records before deploying, and search accuracy may vary with simplified/traditional conversion and text encoding. Before adopting it, verify the data sources, freshness, and license directly in the actual repository.
Sources
- Original post by Gk (@0xGky): 400,000 classical Chinese poems packaged as an API