billion-context: Hierarchical Context Compression Proxy for Long Coding Agent Sessions
Discover billion-context, an open-source proxy tool that leverages acp-kernel hierarchical summarization to sustain long-running agent sessions in 100K token wi
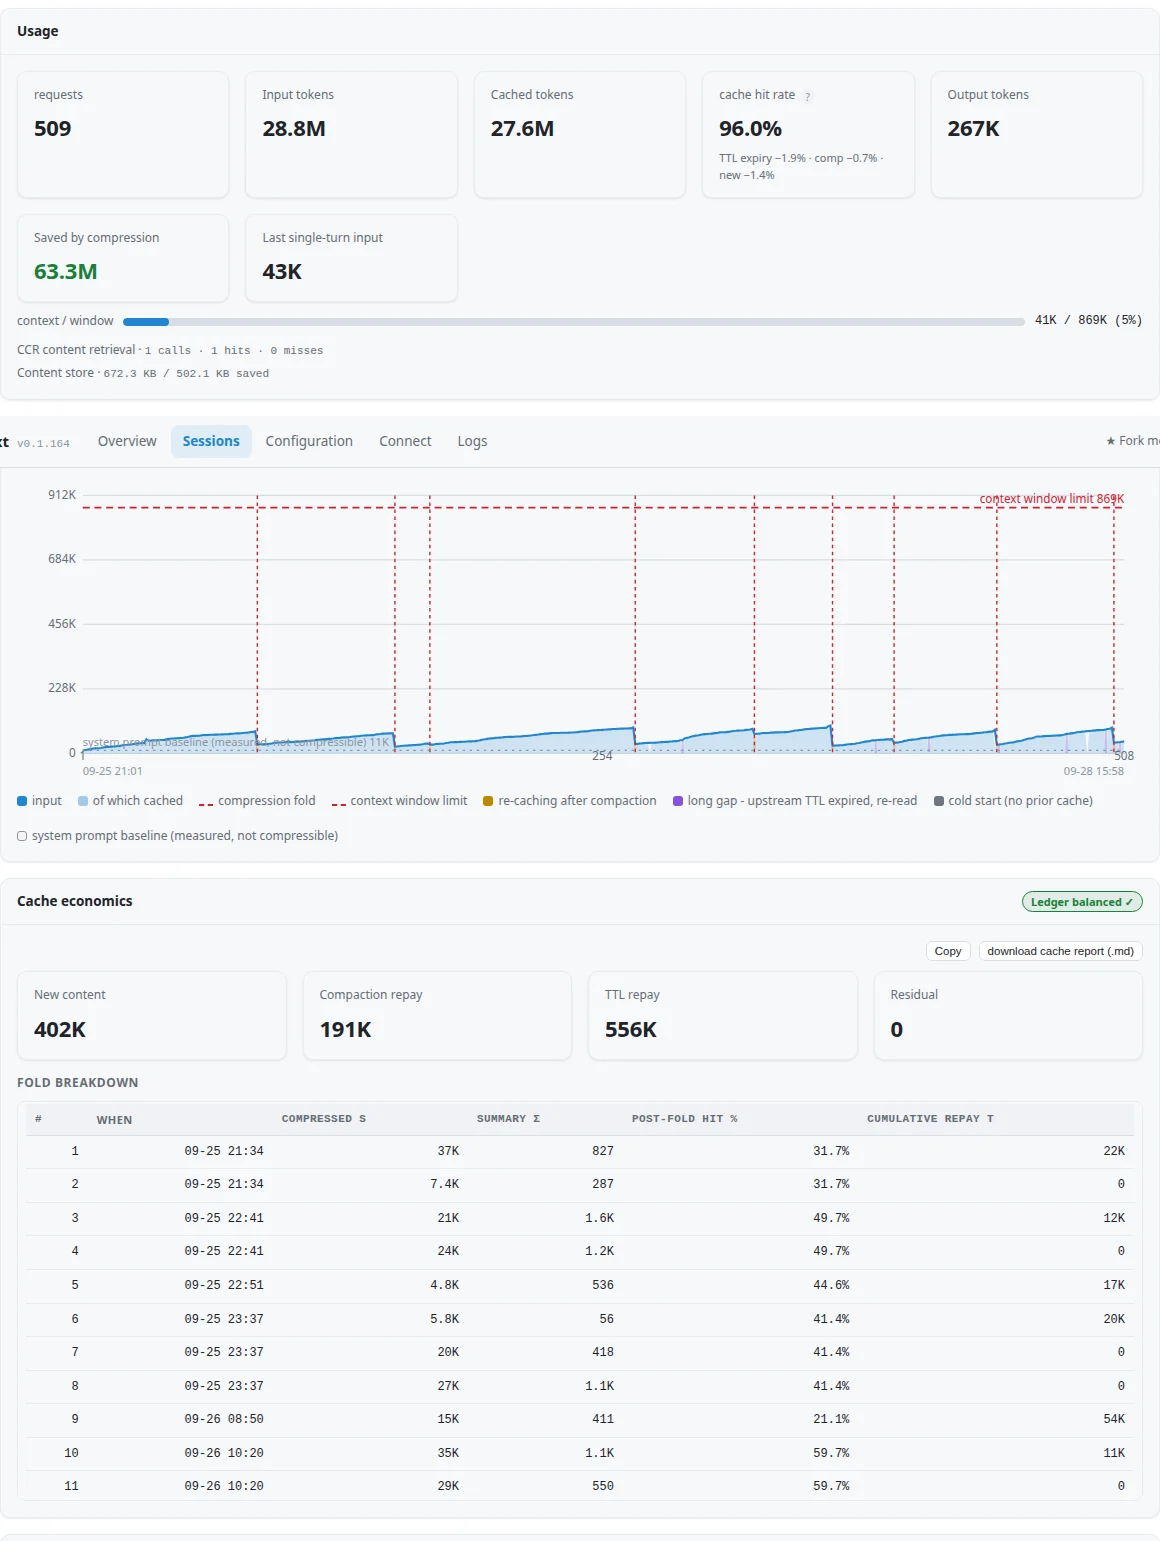
Extended coding sessions often break down as chat histories balloon, quickly hitting context window limits and inflating API token costs. Open-sourced in August 2026 and updated to v0.1.212 on November 2, 2026, billion-context sits between agent clients and upstream model APIs to address these memory bottlenecks.
Image source: https://github.com/ranxianglei/billion-context
Unlike conventional truncation or blunt whole-history summarization methods, billion-context applies hierarchical progressive compression via acp-kernel. This architecture enables multi-day coding workflows even within relatively constrained 100K token windows.
The acp-kernel Proxy Architecture and Model-Driven Context Trimming
billion-context operates as an intermediary reverse proxy. Users configure their agent CLI's API base URL to route through the local proxy instance.
- Stream Interception and Rewriting: Real-time parsing of Anthropic and OpenAI compliant SSE streams applies acp-kernel compression algorithms directly to conversation histories.
- Prefix Cache Friendliness: The proxy avoids whole-history rewriting by compressing older turns into localized summary blocks, helping maintain an upper prefix-cache hit rate around 95–97%.
- Model-Led Compaction Decisions: Rather than enforcing blind rule-based truncation, the tool equips the language model with contextual guidance and specific functions, letting the model decide when and how to fold conversation ranges.
The project reports a 5x reduction in cumulative token consumption based on its self-reported 4.5-month longitudinal benchmark spanning 174,327 model calls. Actual efficiency gains may vary depending on prompt structure and cache reuse.
Four Native Tools for Reversible Context Management
The proxy injects four specific context management tools into the session to balance summarization with precision.
compress: Folds designated message ranges into dense summary blocks.decompress: Reconstitutes compressed blocks back into raw messages when full code snippets or logs are needed again.search_context: Conducts keyword searches across active messages and compressed historical blocks.acp_status: Provides an operational overview of context occupancy and identifies compressible ranges.
Because compressed data is stored within the proxy layer, historical context remains reversible whenever deeper analysis requires original details.
Supported Ecosystem and Integration Trade-offs
Installed via npm (npm install -g billion-context --prefix=~/.local), billion-context provides broad client support across modern CLI tools.
- Client Compatibility: Works with Claude Code, Codex, pi, OpenCode, omp, dsh, and Kimi through launcher wrappers (
bili <client>) or direct plugin configurations. - Integration Constraints: While environments like pi and OpenCode offer inline or native extension paths, other CLI tools (such as jcode or specific versions of Kimi) require attachment via dedicated launchers or cert-MITM proxies.
For engineering teams working on massive refactors or multi-step debugging across large codebases, billion-context provides a practical architectural approach to managing context constraints.
Sources
- ranxianglei/billion-context GitHub Repository: https://github.com/ranxianglei/billion-context