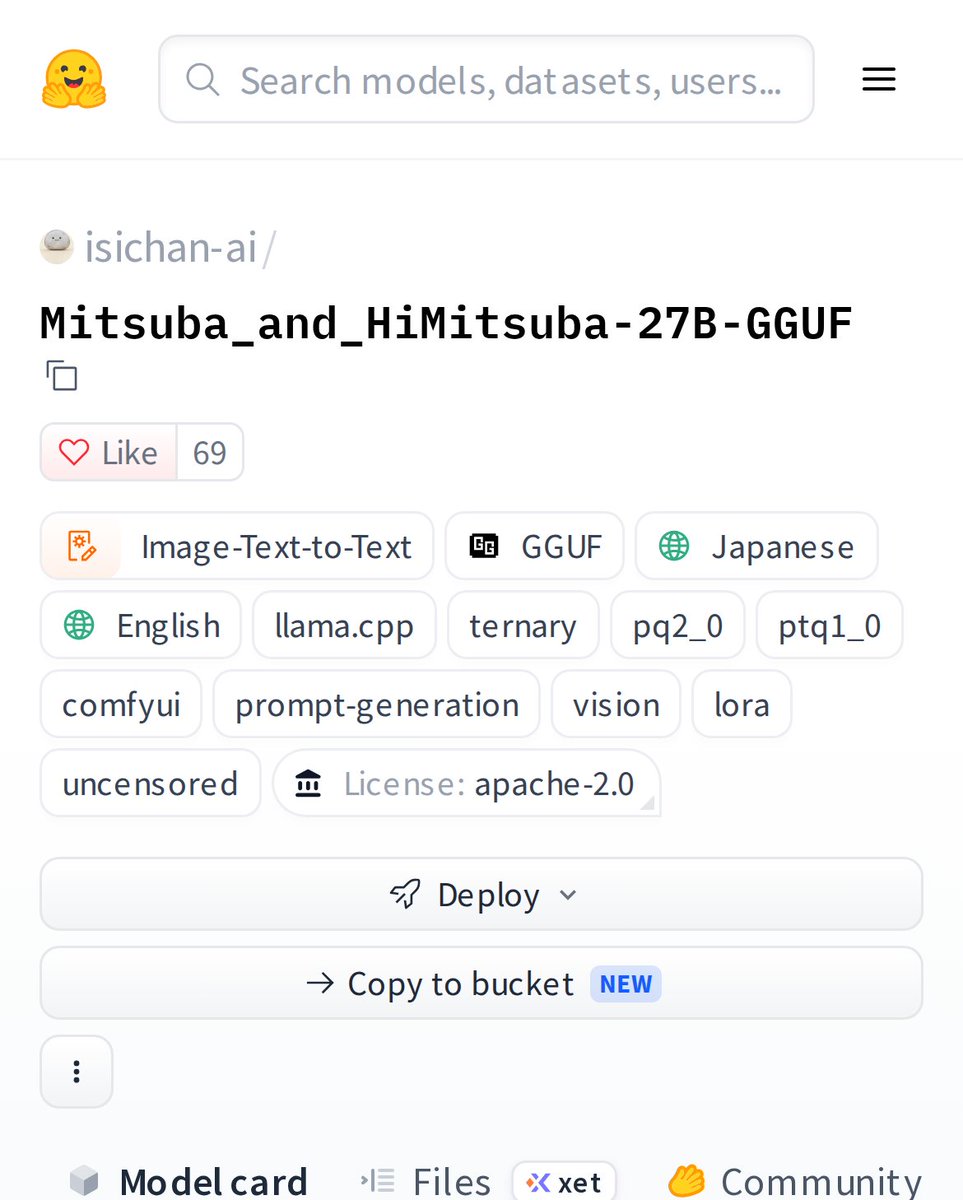
Mitsuba & HiMitsuba 27B GGUF: A 1.58-Bit Vision-Language Model for ComfyUI on 16GB GPUs
Mitsuba and its uncensored HiMitsuba LoRA compress Qwen3.8-27B into a 7.3GB 1.58-bit VLM, enabling fast local image analysis and prompt generation for ComfyUI o
TAU-HOME.COM stories tagged llamacpp.
Mitsuba and its uncensored HiMitsuba LoRA compress Qwen3.8-27B into a 7.3GB 1.58-bit VLM, enabling fast local image analysis and prompt generation for ComfyUI o
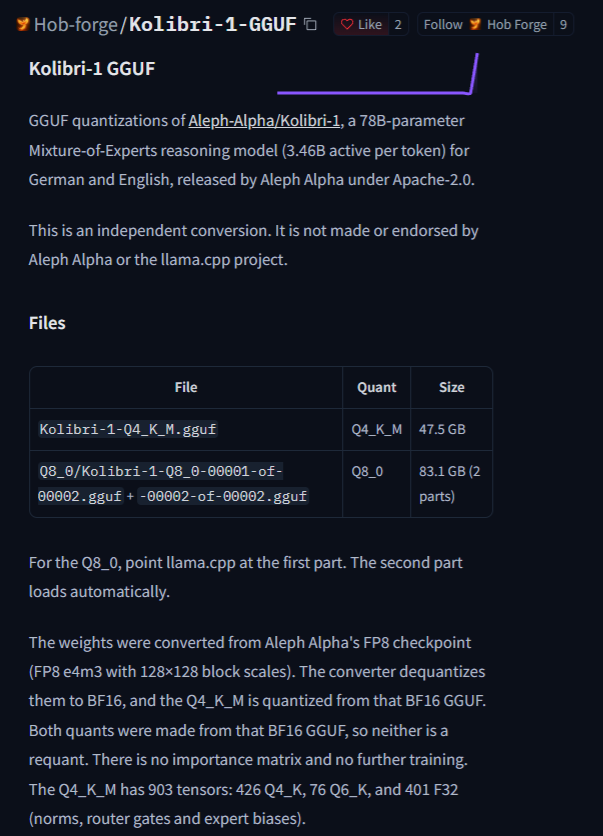
Community GGUF quantizations for Aleph Alpha's 78B MoE model Kolibri-1 are now available, achieving 13-15 TPS on a Ryzen 7 7800X3D CPU using 128GB RAM and patch
Empirical benchmark results comparing local LLM inference speeds (tok/s) and Time to First Token (TTFT) across RTX 5060 Ti (16GB), RTX 5090 (32GB), and GB10 (12
An uncensored GGUF build of Nex-N2.5-mini (IQ4_XS) enables local execution on an 18GB GPU. Explore its 35B MoE architecture, 262K context, vision mmproj, and ll
A guide to 10 open-source repositories driving the AI boom, covering high-throughput serving, local execution, unified gateways, vector search, and distributed
Impact-Site-Verification: 9b3ebd10-6c45-44cf-a014-5b8c19b7b285