Retriever-Free Retrieval: Replacing Vector RAG with Decision Models
An overview of @mm_0824_kb's summary of the 'Retriever-Free Retrieval' paper: a 3-step document retrieval process using decision models as an alternative to vec
An X post by @mm_0824_kb summarizes the paper "Retriever-Free Retrieval: Navigating Documents with Decision Models" as a decision-model approach to document search in place of vector RAG.
Image source: @mm_0824_kb
According to @mm_0824_kb, the method is fast and relatively inexpensive.
3-Step Retrieval Mechanism
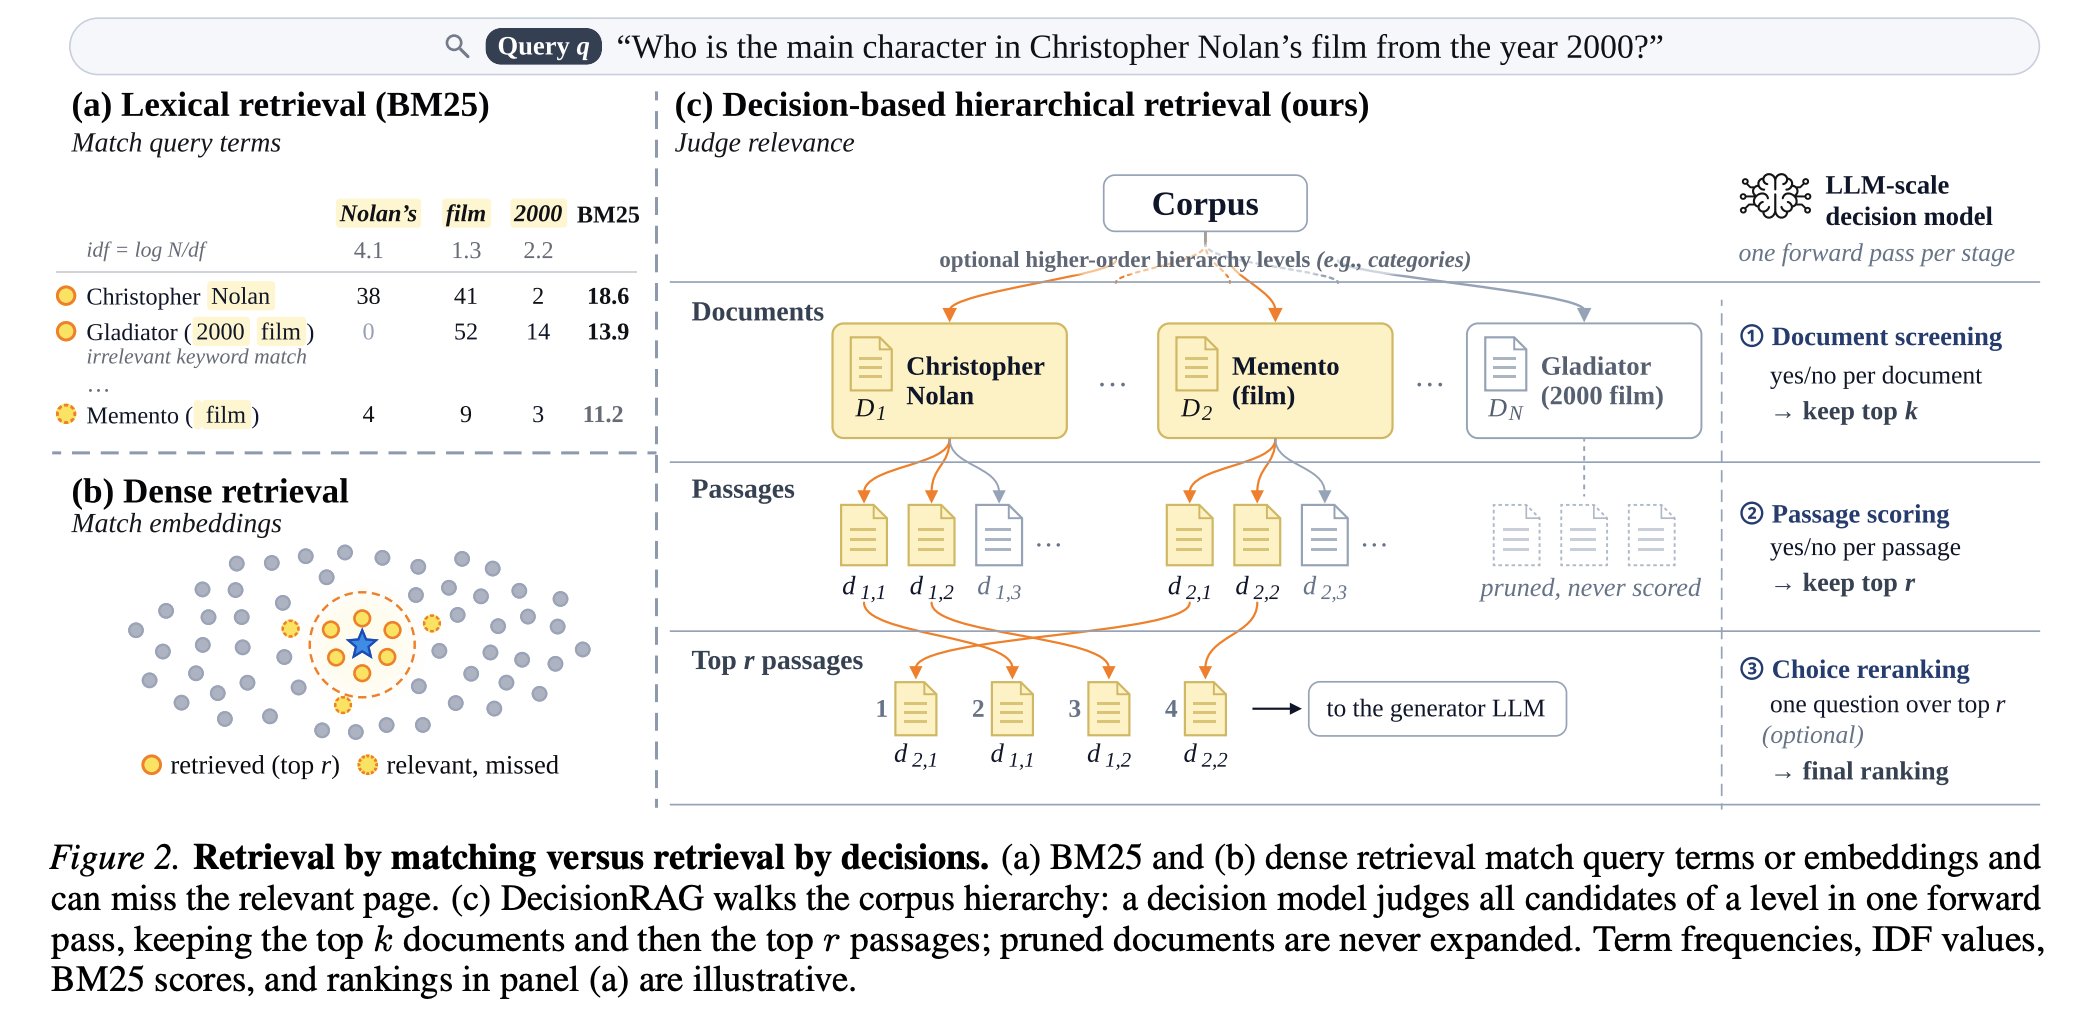
The post summarizes the core pipeline in three stages:
- Step 1 (Yes/No Filtering): Evaluate document relevance to the query with binary Yes/No decisions and select the top $k$ documents.
- Step 2 (Paragraph Extraction): Assess individual paragraphs within the selected documents to extract the top $r$ paragraphs.
- Step 3 (Multiple Choice Reranking): Perform final candidate reranking using a multiple-choice evaluation format.
A reply to the post observes that filtering with Yes/No before paragraph reranking can concentrate inference on needed areas, while top $k$ and top $r$ can tune the balance among accuracy, speed, and cost.
Design Considerations and Practical Implications
@mm_0824_kb notes that if the correct document is dropped from the initial top $k$, later stages cannot recover it, so the cutoff matters.
In the thread, @mm_0824_kb says decision models alone may work for hierarchical, limited-size data, while a hybrid approach may be better for large datasets.