Liquid AI Releases Open-Weight LFM2.5-24B-A2B Model with 2B Active Parameters
Liquid AI has released LFM2.5-24B-A2B on Hugging Face, an open-weight model activating only 2B of its 24B total parameters. Benchmark evaluations show it perfor
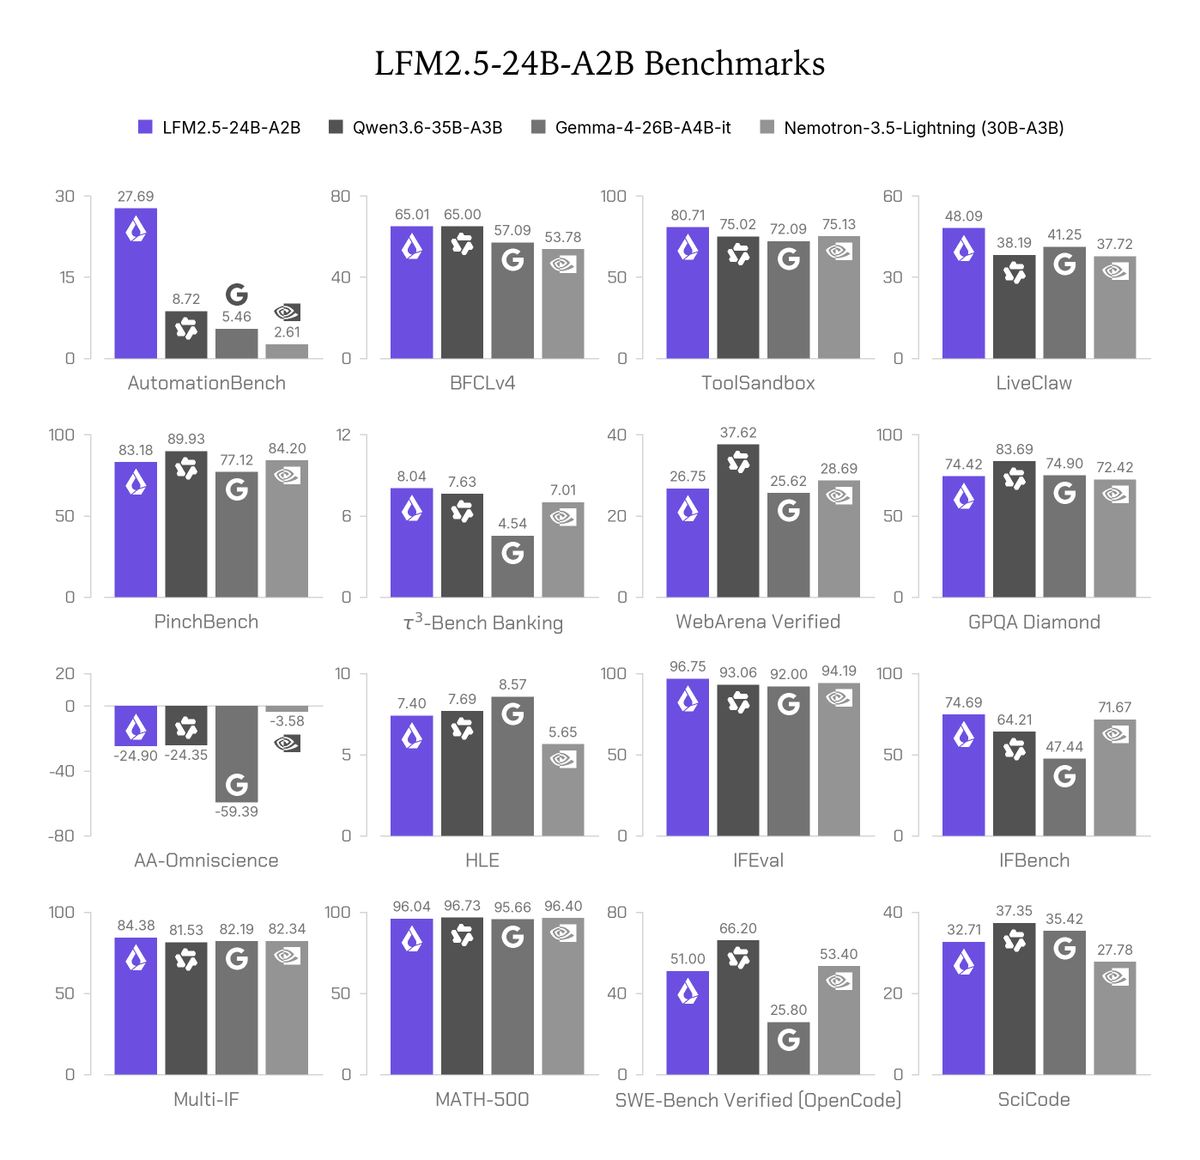
On October 14, 2026, AI research startup Liquid AI officially unveiled LFM2.5-24B-A2B, a new open-weight model in its LFM2.5 series, making weights publicly available on Hugging Face.
Image source: @testingcatalog / Liquid AI
The release features a sparse architecture that activates approximately 2 billion (2B) parameters per token out of a 24 billion (24B) total parameter footprint. By curbing per-token computation to the 2B scale, the model is engineered to provide efficient agentic tool execution in local environments.
24B Total Parameters with 2B Active: Sparse Computation Architecture
The primary architectural characteristic of LFM2.5-24B-A2B is computational efficiency, preserving the parameter footprint of a larger model while reducing actual per-token forward-pass workloads to a 2B tier.
During inference, the model does not engage all 24B parameters for every token; instead, it dynamically routes tokens across roughly 2B active parameters.
- 24B Total and 2B Active Parameters: While the overall parameter structure spans 24B, computation per token is concentrated within approximately 2B active weights, significantly lowering floating-point operations (FLOPs) and power consumption during inference.
- Open-Weight Availability: By releasing weights on Hugging Face, Liquid AI allows developers to test and run the model in private execution environments and local quantization workflows without cloud lock-in.
Matching Qwen3.6-35B-A3B on Tool-Use and Agentic Benchmarks
According to the benchmark comparisons published alongside the release, LFM2.5-24B-A2B performs on par with or ahead of the larger Qwen3.6-35B-A3B (35B total, 3B active parameters) on several key agentic and tool-use evaluations.
The released benchmark chart details the following measurements:
- Tool Use and Function Calling: On the BFCLv4 function-calling benchmark, LFM2.5-24B-A2B scored 65.01, matching Qwen3.6-35B-A3B (65.00). On ToolSandbox, it reached 80.71, exceeding Qwen3.6-35B-A3B (75.02), Gemma-4-26B-A4B-it (72.09), and Nemotron-3.5-Lightning (75.13).
- Automation and Instruction Following: It recorded 27.69 on AutomationBench (Qwen: 8.72), 48.09 on LiveClaw (Qwen: 38.19), 96.75 on IFEval (Qwen: 93.06), and 74.69 on IFBench (Qwen: 64.21).
- Additional Task Comparisons: On MATH-500, it achieved 96.04 (Qwen: 96.73). Conversely, Qwen3.6-35B-A3B outperformed LFM2.5-24B-A2B on complex coding and interactive tasks, including SWE-Bench Verified (OpenCode) at 66.20 versus 51.00, WebArena Verified at 37.62 versus 26.75, and GPQA Diamond at 83.69 versus 74.42.
Full 24B Memory Footprint and Early Community Feedback
When considering local deployments for LFM2.5-24B-A2B, developers should distinguish between active compute speed and total memory footprint, as well as early real-world feedback.
Memory capacity remains the primary hardware requirement. While inference speed benefits from the 2B active compute profile, running the model requires fitting all 24B parameter weights into system RAM or VRAM. Community participants noted that holding the full 24B footprint in memory is the practical hardware threshold for local execution.
Furthermore, early community evaluation highlighted nuances between standardized benchmarks and hands-on harness performance:
- Synthesizing Tool Outputs: In early hands-on testing across MLX Q8 and Pi harness environments on a search-and-fetch factual query, tester M. Kasinski reported that while the model executed tool calls reliably, it struggled to synthesize and digest returned tool data effectively compared to Qwen3.6-35B.
- Workflow-Specific Validation: Rather than relying exclusively on leaderboard metrics, teams evaluating the model are encouraged to test it against concrete local workloads—such as batch translation or structured transformations—where the lightweight 2B compute profile delivers measurable efficiency.
Sources
- Liquid AI Official Announcement on X: LFM2.5-24B-A2B Release Announcement
- TestingCatalog (@testingcatalog): Liquid AI LFM2.5-24B-A2B Benchmark Analysis and Open Weights Release