Hugging Face Turns OpenAI Math Problems into Open-Source RL Environments
Hugging Face's CEO announced open-source reinforcement-learning environments built from OpenAI's math problems. He also disclosed the early limitation: the veri
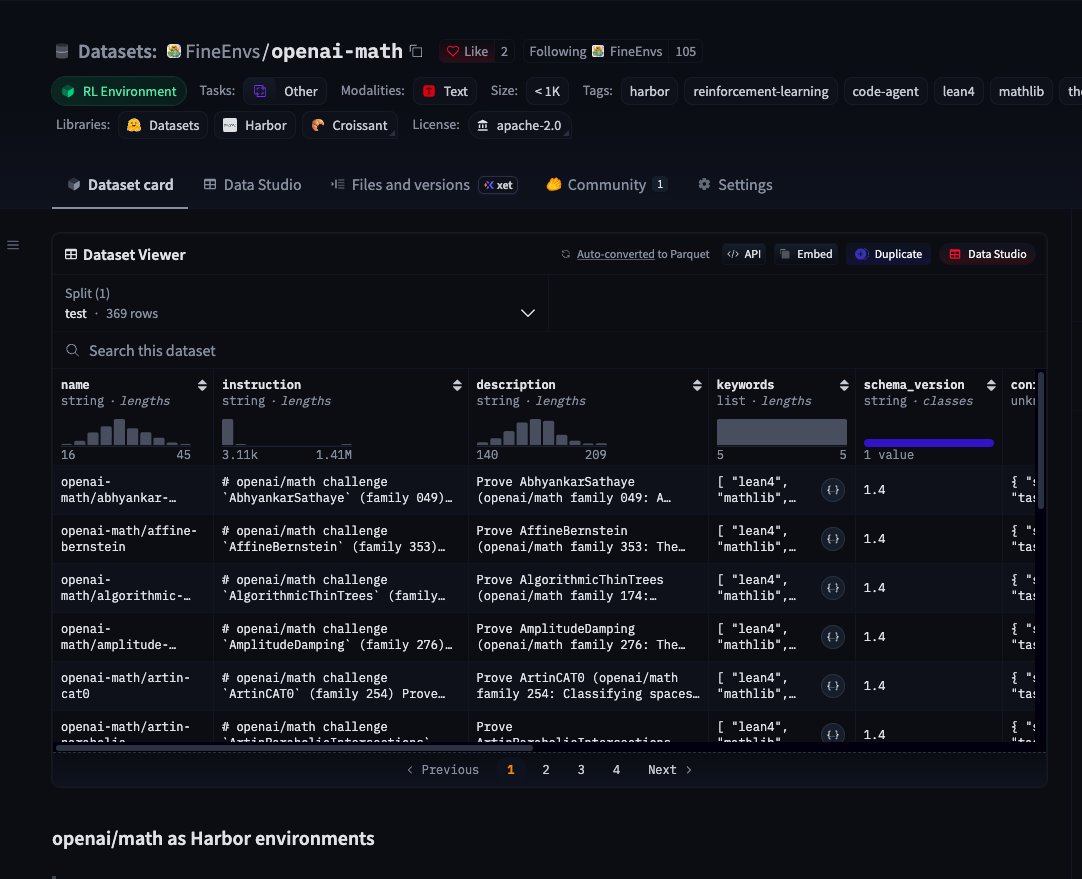
Hugging Face CEO Clement Delangue (@ClementDelangue) announced on October 11, 2026, in an X post that OpenAI's math problems have been packaged as open-source reinforcement-learning (RL) environments on Hugging Face. The framing: turning an open research release into executable training infrastructure that anyone can build on to train better open models.
What was released
According to the original post, the core of this release is OpenAI's math problems repackaged as open-source RL environments. Delangue described it as "what it looks like when a research release becomes executable training infrastructure for everyone," pointing to a direction where open research ships as runnable environments rather than static artifacts.
The natural audience is open-model developers and researchers who want to improve math reasoning through reinforcement learning. It fits teams that want to run training loops against an environment and reward signal, not just score a static benchmark.
The early limitation: a strict verifier
Delangue explicitly labeled the release as early and rough. The verifier only accepts the exact original formalization, so an equivalent proof can still score zero.
That limitation became the immediate talking point in the replies. One user joked that the strict environment recreated a high-school math teacher; another argued that unsupported and wrong proofs should produce different results; a third suggested keeping rejected proofs, since a better verifier could turn some failures into useful training examples. These are community reactions to the announcement, not independently verified facts about how the verifier behaves.
What remains unverified
The shortened link attached to the post was not resolved to its final destination in this desk memo, so the canonical repository URL, license, problem count, and install/usage procedure are unconfirmed. Third-party claims in the replies about row counts or tech stacks were not adopted as facts. No supplementary web search was performed, so there is no cross-verification. Before adopting it, confirm the repository address, license, and usage docs at the link's final destination.
Sources
- clem (Clement Delangue, verified account) X post (Oct 11, 2026): We turned @OpenAI's math problems into open-source RL environments on @huggingface!