Google Unveils Gemini 4 Argon: Leading in 14 of 19 Benchmarks with Gemini Pro Rollout
Google has announced frontier model Gemini 4 Argon and rolled it out to Gemini Pro users, leading in 14 of 19 benchmarks across legal, finance, and 1M context w
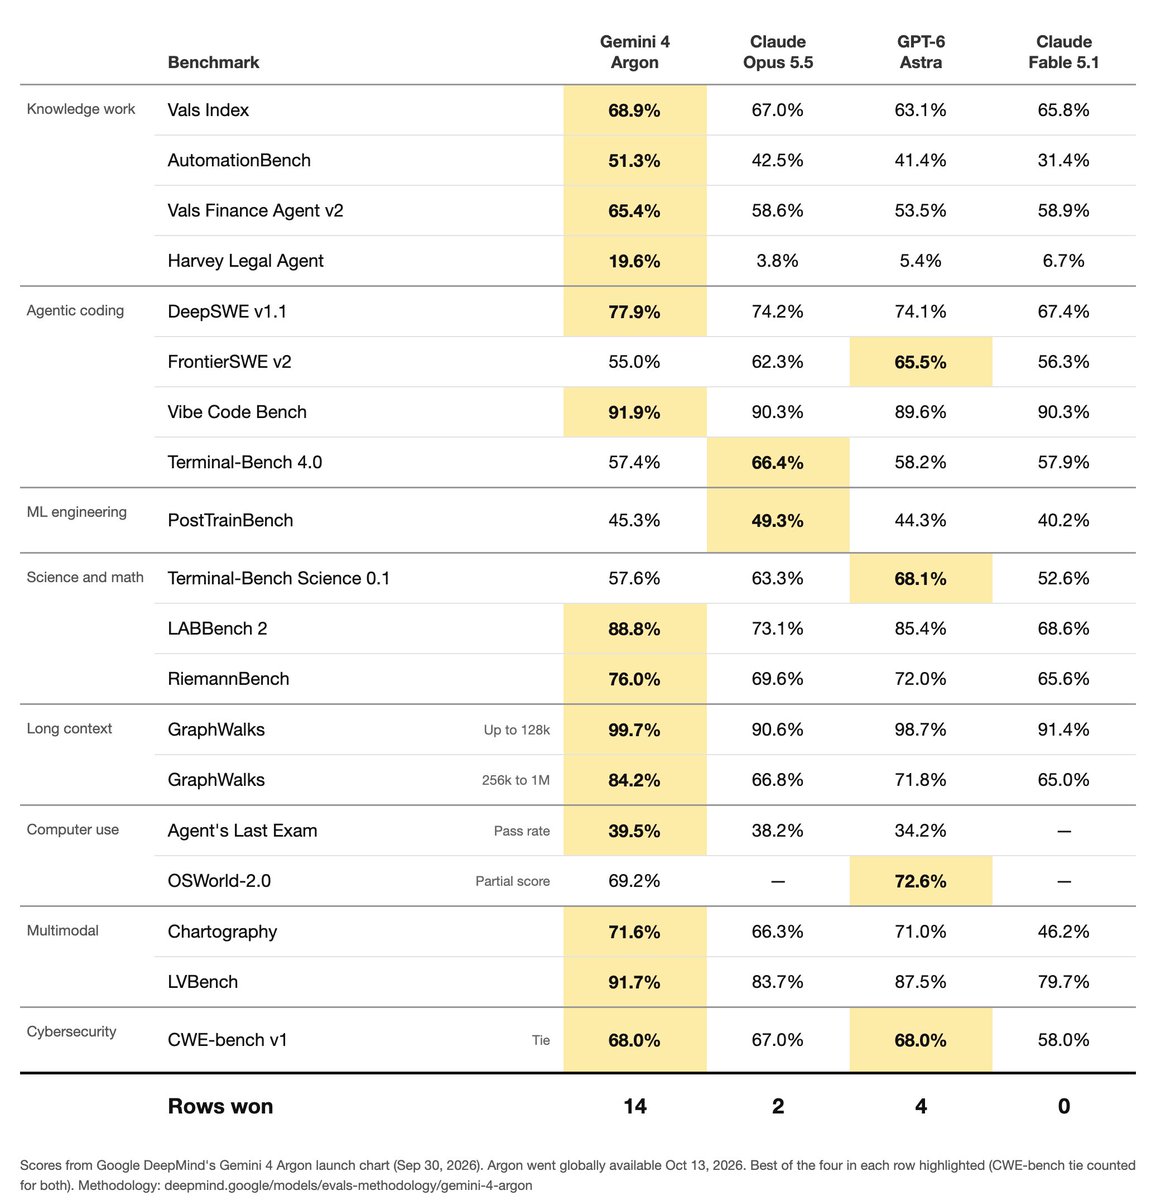
On October 13, 2026, Google officially unveiled its next-generation frontier AI model, Gemini 4 Argon, making it immediately available to Gemini Pro subscribers. The announcement highlights significant benchmark gains across enterprise domains, positioning the model as a frontrunner in legal, finance, and business agent workflows as well as ultra-long-context analysis.
Image source: @alex_prompter via X
According to the comprehensive scorecard published by Google, Gemini 4 Argon outperforms leading frontier models from Anthropic and OpenAI in 14 out of 19 evaluated benchmark tests. Notably, Argon demonstrates sharp improvements in specialized domain agents that combine complex legal reading and numerical reasoning. However, in core developer and software engineering workflows, rival models such as Claude Opus 5.5 and GPT-6 Astra continue to maintain their established edge.
Gains Across Legal, Finance, Business Automation, and 1M Token Context
The benchmark areas where Gemini 4 Argon showed its most decisive advantages center on structured enterprise workflows and long-document processing.
- Legal Agent Work: Gemini 4 Argon achieved a score of 19.6%, nearly tripling Claude Fable 5.1’s 6.7%.
- Business Automation: In business workflow automation evaluations, Argon scored 51.3%, pulling ahead of Claude Opus 5.5 (42.5%) by an 8.8 percentage point margin.
- Finance Agent Work: In quantitative analysis and financial reporting tasks, Argon reached 65.4%, outpacing Claude Fable 5.1’s 58.9%.
- Long Documents Up to 1M Tokens: When evaluating context retention and extraction across documents up to 1 million tokens, Argon scored 84.2%, well above GPT-6’s 71.8%.
According to the published scorecard, Gemini 4 Argon posted its strongest gains in benchmarks associated with legal and financial agent tasks, business automation, and large-scale document analysis.
Coding, Software Engineering, and Computer Use: Rivals Maintain Their Edge
Despite Argon’s strong showing in business automation and long-document processing, developer-focused benchmarks reveal that Claude and GPT models retain their lead in terminal environments and software construction.
- Terminal Coding: In command-line execution and iterative terminal scripting, Claude Opus 5.5 scored 66.4% compared to Argon’s 57.4%, maintaining a 9.0 percentage point lead.
- ML Engineering: In machine learning experiment structuring and code implementation, Claude Opus 5.5 led with 49.3% versus Argon’s 45.3%.
- Software Engineering: On repository-scale software maintenance and complex engineering tasks, GPT-6 Astra achieved 65.5%, outperforming Argon’s 55.0% by 10.5 percentage points.
- Computer Use: In OS-level GUI interaction and desktop application control, GPT-6 Astra reached 72.6% over Argon’s 69.2%.
These results highlight a distinct domain divide: while Gemini 4 Argon excels in high-context document analysis and enterprise agent logic, developers relying on autonomous coding agents, terminal workflows, and full-stack software refactoring will find Claude Opus 5.5 and GPT-6 Astra more attuned to their technical requirements.
Immediate Gemini Pro Availability and Verification Considerations
Alongside the technical unveiling, Google made Gemini 4 Argon immediately available to Gemini Pro subscribers today.
- Immediate Gemini Pro Rollout: Active Gemini Pro users can access Gemini 4 Argon today within their account, enabling immediate real-world testing.
- Scorecard Verification: Because the 14-of-19 benchmark lead is based on Google’s internally authored scorecard, AI practitioners and enterprise evaluation teams note that third-party independent validation remains critical before declaring a definitive shift in the frontier model hierarchy.
For organizations handling complex legal, financial, and multi-document synthesis, Gemini 4 Argon offers an immediate performance upgrade via Gemini Pro, while engineering teams are advised to run side-by-side evaluations against their established coding stacks.
Sources
- Google Official Blog: Introducing Gemini 4 Argon
- Alex Prompter Official X: @alex_prompter Gemini 4 Argon Benchmark Analysis and Scorecard