DeepSeek Open-Sources DeepInfer Inference Framework
DeepSeek has open-sourced DeepInfer, the inference framework used in its production services, with an offline inference release supporting DeepSeek-V4.1-Flash.
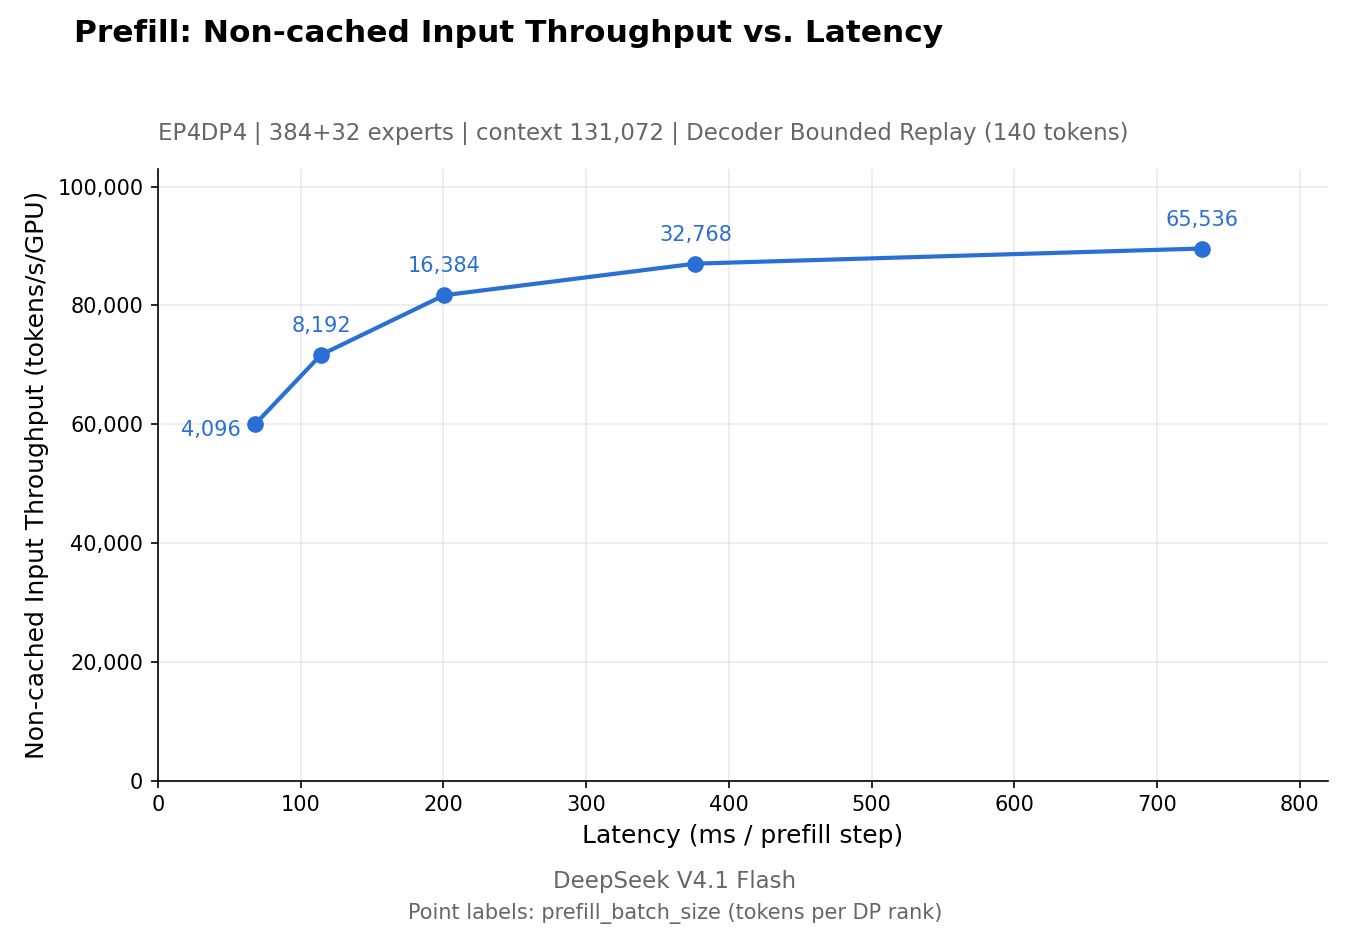
Image: Prefill benchmark chart from DeepInfer's official repository (doc/images/prefill_pareto.png).
Production Architecture and Hardware Support
DeepSeek has released DeepInfer under the Apache License 2.0, open-sourcing the inference framework that powers DeepSeek's large-scale production services. DeepSeek characterizes DeepInfer as a high-performance inference engine, with this open-source release targeting DeepSeek-V4.1-Flash offline inference. DeepInfer was originally built primarily on vLLM, with additional inspiration drawn from SGLang and TensorRT-LLM. Hardware support covers NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, running on Linux with GCC 13.0 or higher, Python 3.12, and CUDA 13 on NVIDIA or CANN 9.2 on Ascend.
Kernel Optimizations and Parallel Execution
The framework integrates custom kernels, model components, and sampler runtimes, including FlashMLA, DeepGEMM, DeepEP, TileKernels, DeepSelect, and custom TileLang kernels. DeepInfer coordinates parallel execution using Attention DP, balanced Context Parallelism (balanced CP), and MoE Expert Parallelism with EPLB. It also adds DSpark confidence-scheduled verification for decoding with draft tokens, SWA bounded replay to reduce decoder prefill compute by replaying only a bounded suffix, and default asynchronous zero-overhead batch scheduling overlapping CPU batch scheduling with device execution.
Serving Scope and Production Caveats
While DeepInfer powers live services, the repository notes that this open-source release currently emphasizes offline inference for serving at scale. The default checkpoint is deepseek-ai/DeepSeek-V4.1-Flash-1017, downloaded on first run or set locally via environment variables. A complete online deployment requires external components not included in this release, including a KV cache system, prefill-decode disaggregation (VE/Prefill/Decode disaggregation), and replica load balancing across data-parallel replicas for both prefill and decode stages. On NVIDIA hardware, deterministic sampling, batch-invariant inference, and structured outputs constrained by regex, JSON schema, or EBNF grammar are also supported.