Cursor Discovers Data Tagging Omission in Pre-Release Grok Bot Test, Raising Concerns Over Internal Data Sent to xAI
During pre-release testing of its internal Grok bot, Cursor identified an omission in training data tagging that resulted in internal usage logs being mixed int
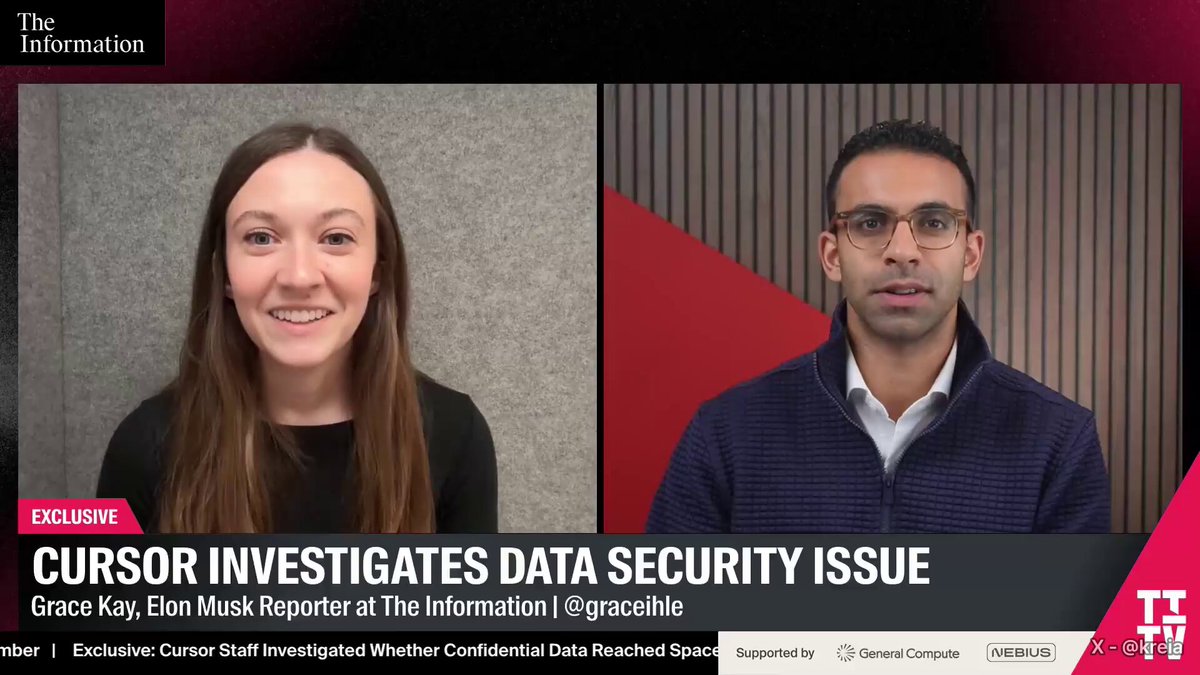
During pre-release development and internal testing of its Grok bot, the engineering team behind AI code editor Cursor discovered an omission in properly categorizing and tagging training data, resulting in internal usage records being mixed into datasets transmitted to xAI. According to reporting from The Information's Grace Eyely, the internal bot had been used across workflows involving customer details and job applicant records, prompting internal concerns over whether sensitive business data was inadvertently shared with the model provider.
Image source: X @kreia / The Information
The development highlights the operational risks inherent in rapidly testing and integrating third-party foundation models internally, particularly when dataset labeling and segregation pipelines fail to fully isolate internal operational logs from external training deliveries.
Training Data Tagging Omission and Dataset Commingling
According to the report, Cursor's development team realized during the pre-release stage of building their Grok bot that data intended for model training had not been systematically distinguished and tagged.
As a result of this tagging oversight, logs generated from internal team members interacting with the Grok bot during daily tasks and testing were inadvertently commingled into data batches dispatched to xAI for model training.
- Missing Training Data Tags: Internal interaction logs and external-bound training datasets lacked the complete tagging and segregation boundaries required during the development phase.
- Commingling into xAI Deliveries: Unmarked internal records were packaged alongside intended training assets and transmitted directly to xAI.
- Internal Discovery and Notification: The issue came to light after Cursor engineers identified the classification gap and began assessing the scope of internal data included.
The incident underscores how minor procedural gaps in data preparation and labeling can directly compromise data governance boundaries when collaborating with external foundation model vendors.
Internal Usage Scope, Sensitive Data Concerns, and Verified Caveats
The primary source of concern within Cursor stems from how the internal Grok bot was deployed across company operations during pre-release testing.
Rather than being confined strictly to code-editing workflows, the bot was also utilized by internal staff handling customer support interactions and processing recruitment candidate evaluations. This broad operational dogfooding raised alarms that customer records or applicant personal details could have been swept into the batches shared with xAI.
However, several critical caveats and factual boundaries govern the situation based on the verified report:
- Sensitive Data Inclusion Not Confirmed: The reporting explicitly characterizes the situation as a concern that sensitive records "might have been included," rather than a confirmed data breach or confirmed exfiltration of personal records.
- Unspecified Scale and Timeline: The exact volume of transmitted data, the precise timeframe of the transfers, and the specific proportion of internal logs involved have not been publicly disclosed or quantified.
- No External Breach or Public Leak: The matter involves data exchange within a pre-release model development partnership between Cursor and xAI, rather than unauthorized third-party intrusion or public data exposure.
Consequently, industry observers categorize the development as an internal governance and pipeline segregation lapse rather than an adversarial security breach.
Data Governance Challenges in AI Dogfooding and Third-Party Pipelines
Internal dogfooding—testing unreleased AI tools and models directly on company workflows—is a standard industry practice to accelerate iteration and ensure product readiness. However, when internal testing environments hook directly into model training pipelines maintained by external partners, the risk of cross-pollinating proprietary business information into model training pools grows substantially.
For organizations building and adopting generative AI assistants, the incident illustrates the critical need for strict logical and physical barriers, automated redaction, and deterministic tagging audits prior to any external data transmission.
As AI development cycles compress, Cursor's experience serves as a clear reminder that data lifecycle governance and rigorous training boundary controls must keep pace with engineering velocity.
Sources
- The Information reporting clip via Kreia Notes on X: Cursor's Grok bot test may have sent private data to xAI